Tag: System

  • MSD0023 YouTube Copyright Detection

    Design the copyright detection system for a video platform like YouTube. Every uploaded video (hundreds of hours per minute) must be scanned against a reference corpus of tens of millions of copyrighted songs, movies, and clips, and matched even when the content is pitch-shifted, cropped, overlaid with voiceover, recorded off a screen, or remixed. The system must return matches within minutes so that rightsholders can block, monetize, or track the use, and it must keep the false-positive rate low enough that legitimate fair use and original content are not wrongly claimed.

    How would you design this system? Cover the audio and video fingerprinting representations, the matching index at scale, the latency and throughput budget for the upload firehose, how you handle partial and transformed matches, and how disputes and appeals are routed.
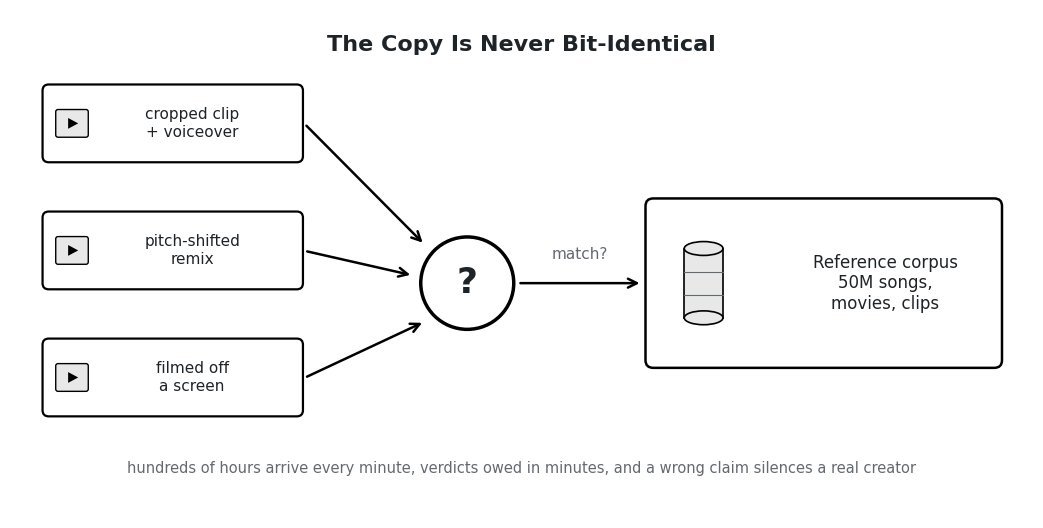
    Line-art scene: transformed uploads (cropped clip with voiceover, pitch-shifted remix, video filmed off a screen) flowing toward a question mark that must be answered against a vault holding a reference corpus of 50 million songs, movies, and clips

    The Problem: the copy is never bit-identical, the corpus is tens of millions of references, the answer is owed in minutes, and a wrong claim silences a legitimate creator.

    Answer

    The design is a two-stage fingerprint retrieval system: cheap, high-recall candidate generation from compact per-modality fingerprints, then strict temporal verification that only accepts a candidate if many hash hits agree on a single time offset. Audio and video are fingerprinted separately because their attack surfaces differ. Audio uses spectral peak landmark hashes plus a neural fallback for pitch and tempo edits, while video uses learned copy-detection embeddings that survive cropping, overlays, and screen recording. The two pivotal decisions are to make the verification stage, not the recall stage, own precision, and to convert model confidence into tiered actions (auto-claim, human review, track-only) so that an uncertain match costs a reviewer’s time rather than a creator’s channel.

    (1) Dual-Modality Fingerprints: audio landmark hashes of the form (f_1, f_2, \Delta t) at roughly 30 hashes per second, and video frame descriptors sampled at 2 to 4 fps after letterbox and border normalization.
    (2) Two-Stage Retrieval: a sharded inverted index (plus ANN search over neural embeddings) proposes a few hundred candidate references per query chunk; verification rejects almost all of them.
    (3) Offset Voting And Segment Stitching: a real match produces a spike in the histogram of t_{ref} - t_{query}; adjacent winning chunks are stitched into segments with a minimum matched duration.
    (4) Chunked Parallel Ingest: uploads are split into 10-second chunks that fingerprint in parallel, with a priority queue so premieres and large channels finish first.
    (5) Tiered Actions: high confidence auto-claims, medium confidence routes to human review or track-only, low confidence is logged and dropped.
    (6) Dispute Loop As Training Data: every appeal outcome becomes a label, feeding whitelists, threshold retuning, and reference-corpus cleanup.
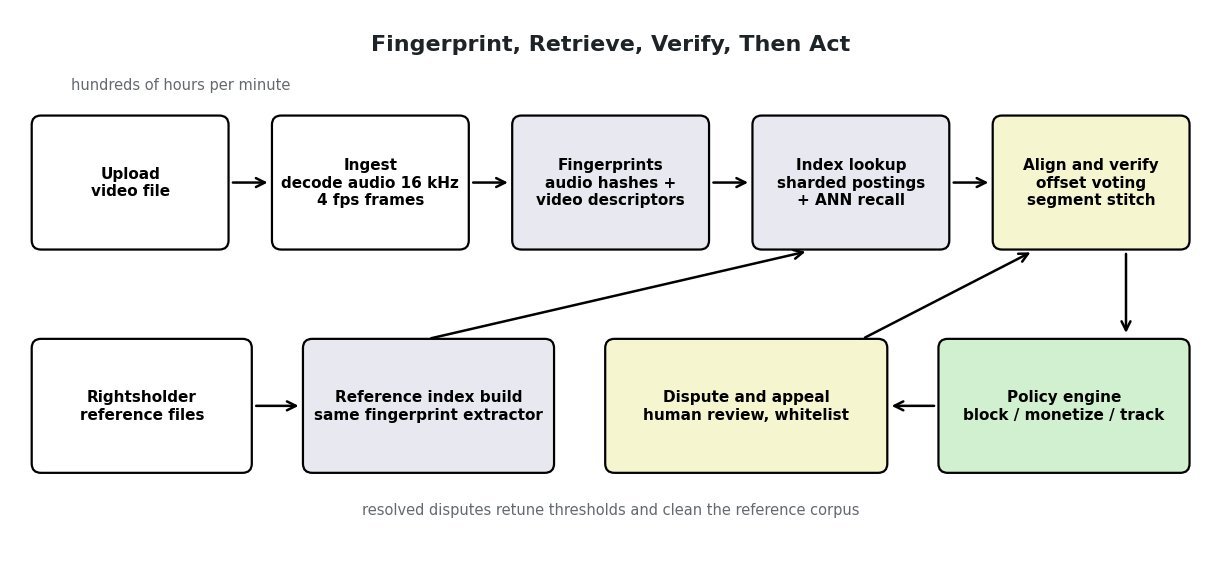
    Copyright detection pipeline: upload flows through ingest and decode, fingerprint extraction, sharded index lookup, and alignment and verification into a policy engine; a lower row shows rightsholder reference files being fingerprinted offline into the index, and disputes feeding thresholds back into verification

    Figure 1: One path for uploads (fingerprint → lookup → verify → policy) and one offline path that fingerprints rightsholder references with the same extractor; disputes flow back from the policy engine into verification thresholds and whitelists.

    Clarify Before Designing:
    (1) Scope Of Rights: do we match sound recordings only, or also compositions and melodies, since a cover song copies the composition without copying any audio?
    (2) Verdict SLA: must the scan block publishing, or may the video go live and be claimed minutes later, and does the SLA differ for monetized channels?
    (3) Corpus Scale And Registration: how many references, how fast is the corpus growing, and who is allowed to register a reference?
    (4) Cost Asymmetry: what false-claim rate is acceptable versus missed detections, and who pays for human review of the uncertain band?
    (5) Transformation Catalog: which edits must be caught (crop, pitch shift, speed change, voiceover, screen capture, remix, AI covers), because that choice decides the fingerprint representation?
    (6) Available Actions: block, monetize, or track, and are the policies territory-specific?

    Login to view more content
  • MSD0022 Model Drift Dashboard

    A large platform runs thousands of ML models in production: ranking models, fraud classifiers, content moderators, recommendation embedders, each with its own feature pipeline, serving path, and delayed-label feedback. A single broken upstream feature, a silent model upgrade, or a gradual distribution shift can degrade any of them for days before anyone notices.

    The ML platform team needs one real-time monitoring system that surfaces drift, performance, and data-quality issues across the entire fleet, with alerting that catches real regressions without drowning on-call engineers in false alarms. How would you design this system? Cover the metrics each model emits, the streaming and storage architecture for thousands of models, the drift and anomaly detection methods that scale across heterogeneous model types, the alerting and triage workflow, and how you measure the monitoring system itself (mean time to detect, alert precision).

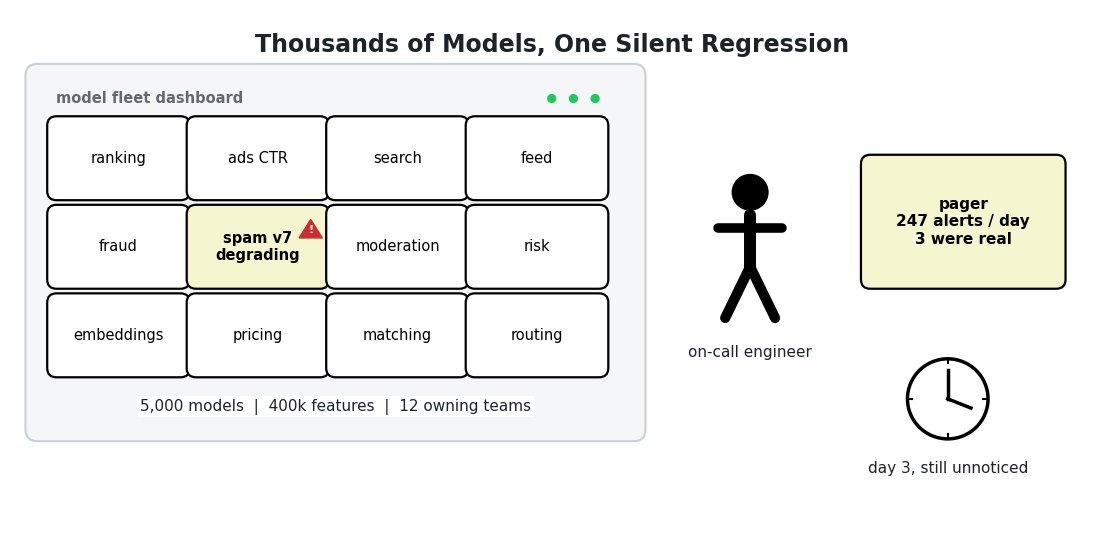
    Line-art scene: a wall of model tiles with one tile quietly marked as degrading, an on-call engineer beside a pager showing hundreds of alerts of which only three were real, and a clock marking three days of silence

    The Problem: one model in a fleet of thousands is quietly getting worse, and the on-call engineer is already ignoring a pager full of alerts that were never real.

    Answer

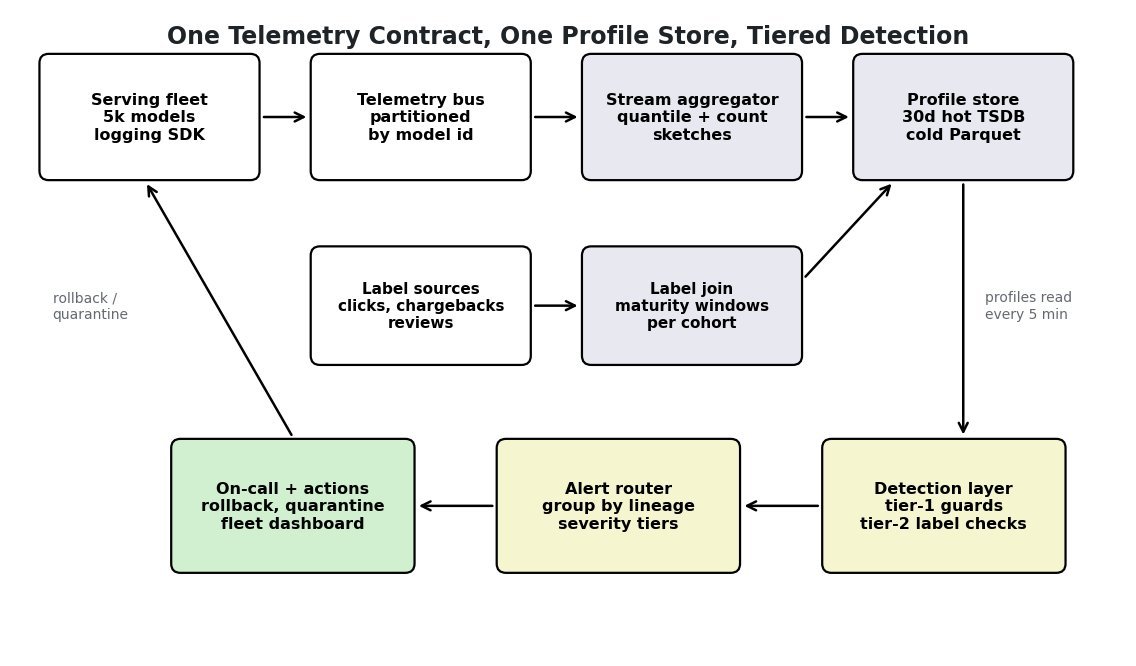
    The design is a fleet-wide observability service with three layers. Every serving path emits a uniform telemetry record through a shared logging SDK, a streaming job compresses those records into per model, feature, slice and window sketches, and a detection layer runs cheap statistical guards on everything plus expensive label-joined performance checks on the models that carry real money. The two pivotal decisions are that detection never scans raw events at query time (it reads compact profiles, which is what makes thousands of models affordable), and that alerting is engineered for precision rather than coverage: a trigger must clear an effect-size floor, persist across several windows, and survive root-cause grouping before it pages anyone. The monitoring system is itself a product with SLOs, scored on mean time to detect and alert precision against continuously injected synthetic regressions.

    (1) Uniform Telemetry Contract: one prediction record schema (model id and version, feature values or hashes, score, slice keys, join key, latency) emitted asynchronously by a sidecar or SDK, so the platform never reimplements logging per team.
    (2) Sketch-Based Aggregation: a streaming job keeps t-digest quantiles, count-min sketches for categoricals, and null/count/cardinality counters per 5-minute window, turning terabytes of events into tens of gigabytes of profiles.
    (3) Tiered Detection: tier-1 data-quality and drift guards run on every model and feature; tier-2 label-joined AUC, calibration, and slice regressions run only on business-critical models.
    (4) Delayed-Label Handling: proxy signals (score distribution, positive rate, confidence) fire in minutes, while true performance is computed on maturity-aware cohorts so immature labels never trigger a page.
    (5) Precision-Engineered Alerting: adaptive seasonal baselines, an effect-size floor, multi-window persistence, and deduplication by feature lineage turn thousands of triggers into a handful of owned incidents.
    (6) Self-Measurement: synthetic drift and corrupted-feature injections give a labeled incident corpus, so MTTD and alert precision are measured, not asserted.

    Fleet monitoring pipeline: serving fleet logs to a telemetry bus, a stream aggregator writes sketches into a profile store, delayed labels join separately, a detection layer reads profiles every five minutes, an alert router groups incidents, and on-call actions feed back to the serving fleet

    Figure 1: Raw predictions are compressed once into profiles; every detector, dashboard, and alert afterwards reads those profiles instead of the event stream.

    Clarify Before Designing:
    (1) Fleet Shape: how many models, how many features each, aggregate QPS, and how many are business-critical versus experimental?
    (2) Detection Budget: is the target time to detect minutes, an hour, or a day, and is it the same for a fraud classifier and a feed ranker?
    (3) Label Latency: per use case, how long until ground truth arrives (clicks in seconds, chargebacks in weeks, moderation appeals in days)?
    (4) Cost Ceiling: what fraction of serving cost may monitoring consume, and can we sample rather than log every request?
    (5) Remediation Authority: may the system auto-rollback a model version or quarantine a feature, or does it only page a human owner?
    (6) Data Constraints: which features are PII or regulated, and what is the retention limit on stored feature values?


    Login to view more content
  • MSD0020 Distributed Training System

    Design the distributed training system for a 100B+ parameter language model on a cluster of thousands of GPUs, the way Meta, OpenAI, and DeepSeek run their frontier models. A single run spans weeks to months, costs millions of dollars in compute, and must survive GPU failures, network bottlenecks, and stragglers without restarting from scratch.

    The system has to combine data, tensor, and pipeline parallelism, checkpoint efficiently, and keep GPU utilization high enough that the run finishes on budget.

    How would you design it? Cover the parallelism strategy and communication topology, fault tolerance and checkpointing, cluster scheduling, and how you diagnose and fix the bottlenecks that keep utilization below target.

    Line-art scene: a 100B-parameter model far too large for a single 80 GB GPU, a grid of thousands of cluster GPUs with one marked as failed, and annotations for weeks of wall-clock and millions of dollars of compute

    The Problem: the model does not fit on one GPU, the cluster is big enough that something breaks every few hours, and every idle GPU-second is billed. The design question is how to keep thousands of accelerators busy on one gradient for a month.

    Answer

    The design is 3D parallelism mapped onto the bandwidth hierarchy, wrapped in an elastic supervisor that treats hardware failure as a routine event. Tensor parallelism stays inside a node where NVLink is cheap, pipeline parallelism crosses nodes because only stage activations travel, and data parallelism with sharded optimizer state sits outermost where the gradient all-reduce can be overlapped with the backward pass. Fault tolerance is asynchronous distributed checkpointing at a mathematically chosen interval plus a hot-spare pool, so a dead GPU costs minutes rather than the run. The single number the whole system is managed against is MFU (model FLOPs utilization), because at this scale every lost percentage point is real money, and every design choice below is justified by its effect on that number.

    (1) Bandwidth-Matched Parallelism: tensor parallel degree capped at the intra-node GPU count, pipeline parallel across nodes, data parallel outermost; context parallelism added only when sequences get long.
    (2) Sharded State And Selective Recompute: optimizer states and gradients sharded across the data-parallel group, with selective activation recomputation trading roughly 8% extra FLOPs for the memory that makes the fit possible.
    (3) Async Checkpointing At The Optimal Interval: copy state to host memory in seconds, flush to storage in the background, and set the interval from measured cluster MTBF instead of habit.
    (4) Elastic Recovery With Hot Spares: a watchdog detects hangs and stragglers, a spare node replaces the failed one in place, and training resumes from the last checkpoint including data-loader position.
    (5) Topology-Aware Gang Scheduling: the job is placed inside one network island as an all-or-nothing gang, after a preflight burn-in that rejects slow links and weak GPUs before the run starts.
    (6) MFU As The Run’s SLO: per-rank step-time histograms, profiler traces, and a loss budget that attributes every missing point of peak FLOPs to a named cause.

    Training system pipeline: token shards feed a resumable loader into a 3D-parallel training step, then gradient reduction and sharded optimizer update, then async checkpointing to a checkpoint store, with a health watchdog and hot-spare pool closing the recovery loop

    Figure 1: One step is load → forward → backward → reduce → update → stage checkpoint. The lower loop is what makes a month-long run survivable: detect, replace, restore.

    Clarify Before Designing:
    (1) Hardware And Interconnect: how many GPUs per node, what intra-node link (NVLink or PCIe), and what inter-node fabric bandwidth per GPU?
    (2) Token Budget And Deadline: how many training tokens, and is the constraint calendar time, total GPU-hours, or dollars?
    (3) Sequence Length: is context 8k or 128k, because long context changes activation memory and adds a whole parallelism axis?
    (4) Precision Policy: is FP8 or BF16 allowed for GEMMs, and what loss-curve deviation from a reference run is acceptable?
    (5) Storage And Checkpoint SLA: what aggregate write bandwidth exists, and how much lost work per failure is tolerable?
    (6) Cluster Ownership: dedicated reservation or shared preemptible pool, and how large a hot-spare pool can be held idle?


    Login to view more content
  • MSD0018 Ads Policy Violation Detection

    Design an end-to-end ML system to detect ads selling weapons and other policy-violating goods on a large ads platform like Meta or Google Ads. Millions of new ad creatives arrive daily as text, images, and video, and advertisers constantly adapt their creative to evade detection. Google’s Ads Safety Report describes blocking or removing billions of ads per year, so this is an industrial-scale enforcement problem, not a one-off classifier.

    The system must block prohibited ads before they serve, route borderline cases to human reviewers, and keep the false-positive rate low enough that legitimate advertisers are not churned.

    How would you design this system? Cover the multimodal detection model, the human-review queue prioritization, the adversarial adaptation problem, and how you measure recall and precision at platform scale.

    Line-art scene: a stack of text, image, video, and carousel ad creatives feeding a gate that must decide allow or block before the first impression, with one path serving millions of impressions and the other path never allowed to serve

    The Problem: millions of new creatives arrive every day, roughly one in ten thousand is a prohibited-goods listing, and the decision must be made before the ad is shown even once.

    Answer

    The design is a pre-serve multimodal gate inside the ad-ingestion path. A cheap first stage kills known-bad creatives by hash and embedding near-duplicate lookup, then a shared vision-language encoder with per-policy heads scores every creative (ad copy, OCR text, landing-page text, image, video keyframes) before the first impression. Each policy class gets three calibrated bands: auto-block, human review, allow. Two decisions carry the design. First, thresholds are set from the asymmetric cost of a served weapon ad versus a wrongly blocked advertiser, per policy and per locale, rather than from a single global score cut. Second, the whole system is treated as an adversarial loop where the time from a new evasion pattern to a deployed block (hours, not quarters) matters more than static offline AUC.

    (1) Staged Funnel: creative-hash cache and embedding kNN against known violations resolve most repeat traffic in milliseconds; only novel creatives pay for the full multimodal pass.
    (2) Multimodal Model: a frozen vision tower plus a multilingual text tower over copy, OCR, ASR, and landing-page text, fused into multi-label per-policy heads instead of one binary “violating” output.
    (3) Three-Band Decision Policy: per-policy calibrated thresholds split traffic into auto-block, review, and allow, so precision on the auto-block band is protected by construction.
    (4) Expected-Harm Review Ranking: the reviewer queue is sorted by violation probability times forecast impressions times policy severity, not by score alone, and clusters of near-duplicate creatives collapse into one decision.
    (5) Adversarial Response Loop: evasion signals (re-upload similarity, account bursts, appeal patterns) feed hard-negative mining, an embedding blocklist hotfix within hours, and account-level enforcement that raises the attacker’s cost.
    (6) Measurement by Sampling: recall is estimated from stratified random audits of allowed traffic, precision from reviewer audits of blocks and from appeal-overturn rates.

    Pipeline: ad ingest, asset extraction with OCR and ASR, encoders, fusion head with per-policy scores, decision policy fanning out to allow-and-serve, auto-block, and a review queue; reviewer labels loop back through a label store into retraining, with a near-duplicate index feeding the decision

    Figure 1: Ingest → asset extraction → encoders → per-policy scores → three-band decision, with reviewer labels and the near-duplicate index closing the loop back into the model.

    Clarify Before Designing:
    (1) Scale and Asset Mix: how many new creatives per day, how many assets each, and what share is video (video dominates compute cost)?
    (2) Enforcement SLA: must an ad go live within minutes of upload, or is holding a creative for a deep asynchronous pass acceptable?
    (3) Policy Taxonomy: how many prohibited-goods classes, which are legally mandated, and how much do they vary by jurisdiction?
    (4) Cost Asymmetry: what is the tolerated false-block rate before advertiser churn becomes the bigger loss, and what is the appeal SLA?
    (5) Review Capacity: how many reviewer hours per day, in which languages, and with what accuracy on gold sets?
    (6) Label Availability: do we have historical enforcement decisions, appeal outcomes, and account-level history, or are we starting from policy text only?


    Login to view more content
  • MSD0017 Meeting Summarization

    Design the system behind Zoom AI Companion’s meeting summary: after a 45-minute video meeting, every participant receives a recap, the decisions made, and their action items within a minute or two. The pipeline must handle cross-talk, accents, and bad microphones across ten speakers, and a hallucinated action item is worse than none at all.

    How would you design this system? Cover transcription, speaker attribution, the summarization stack, quality control, privacy, and cost at platform scale.

    Line-art scene: a two-by-two video call grid, a clock showing forty-five minutes elapsed, an empty notepad, and a question mark asking what was actually decided

    The Problem: forty-five minutes of overlapping speech from ten microphones must become a recap, a decision list, and attributed action items, within minutes, and one invented task destroys trust. Design the pipeline that was actually listening.

    Answer

    The design is a staged pipeline with a federated summarization stack, the approach Zoom publishes for AI Companion: streaming ASR turns audio into words, speaker diarization attributes them to people, a post-processing stage restores punctuation and domain terms, and the summarization stage drafts on a small in-house LLM, scores the draft with a learned quality model (Zoom’s Z-Scorer), and escalates to a stronger external LLM only when the score is low. The two pivotal decisions are separating “who spoke” from “what was said” (diarization plus ASR reconciled with the meeting roster, not one giant model asked to guess names) and never paying frontier-model prices for meetings a small model summarizes fine (Zoom reports comparable quality at roughly 6% of GPT-4 cost).

    (1) ASR Frontend: streaming encoder-decoder (Whisper-class) with custom vocabulary biasing for product and people names; about 95% word accuracy on real meetings.
    (2) Speaker Diarization: embedding-based turn detection (pyannote-style) reconciled with the participant roster and per-channel audio when available, so “Speaker 2” becomes “Ada”.
    (3) Structured Summarization: chained tasks with schema-checked JSON output: chapter segmentation, recap, decisions, action items with owners.
    (4) Federated Quality Control: small model drafts, a learned scorer predicts summary quality, low scores escalate to stronger LLMs, and a committee-of-LLMs cross-check suppresses hallucinated action items.
    (5) Privacy by Inheritance: summaries inherit the meeting’s access control and retention; a self-hosted-only model path serves regulated customers.

    Meeting summarization pipeline: meeting audio flows through ASR, then diarization, then an attributed transcript, then a summarization stage producing recap decisions and action items, through a quality scorer, to delivery; a dashed escalation path runs from the scorer back to a stronger LLM

    Figure 1: The pipeline: hear the words, attribute them, then summarize with schema-checked structure; the scorer, not blind trust, decides when a stronger model is worth paying for.

    Clarify Before Designing:
    (1) Live versus Post: in-meeting “catch me up” queries (seconds, incremental) or post-meeting delivery only (minutes, batch)?
    (2) Language Scope: English only, or 30-plus languages via translation assists or multilingual models?
    (3) Identity Source: is a participant roster, per-channel audio, or voice enrollment available, or must speakers stay anonymous labels?
    (4) Worst Error: which failure is most expensive here: hallucinated action items, missed decisions, or wrong attribution?
    (5) Scale and Budget: meetings per day, average length, and the cost ceiling per meeting-minute?


    Login to view more content
  • MSD0016 Scanned Document OCR

    Design an OCR system that converts millions of scanned documents (contracts, invoices, old books, fax-quality pages) into clean, structured text for a document platform like AWS Textract, Google Document AI, or Mistral’s OCR API. The output must preserve reading order, tables, and equations, not just raw characters, because the text feeds search indexes and RAG pipelines downstream.

    How would you design this system? Cover the recognition approach, layout and structure handling, accuracy measurement, and the cost of processing at scale.

    Line-art scene: a skewed, stained scanned page with two columns, a table, and an equation on one side, clean structured text on the other side, and a question mark over the transformation

    The Problem: a skewed, coffee-stained scan of a two-column contract must come out as correctly ordered, structured text, at millions of pages, at a cost a business can pay. Design the reader that never silently scrambles a page.

    Answer

    The design is a single-pass document VLM pipeline in the style of AI2’s olmOCR: lightweight preprocessing normalizes each page (orientation, deskew, denoise, blank rejection), then a fine-tuned 7B-class vision-language model reads the whole page in one pass and emits structured output (Markdown for headings, HTML for tables, LaTeX for math), and programmatic unit tests verify each page (does the table parse? does the equation recompile? is reading order sane?) before failures are retried or routed to a stronger model or a human queue. The two pivotal decisions are reading whole pages in one pass instead of a detect-then-crop-then-recognize cascade (which accumulates errors and loses reading order), and defining correctness as machine-checkable tests so both evaluation and training optimize what downstream consumers actually need.

    (1) Single-Pass VLM Reader: a fine-tuned Qwen2.5-VL-class model turns a page image directly into structured Markdown/HTML/LaTeX, skipping the multi-stage cascade.
    (2) Document Anchoring: born-digital PDFs contribute their embedded text and metadata into the prompt alongside the page image, grounding the model and cutting hallucination.
    (3) Preprocessing Gate: orientation detection, deskew, denoise, and blank-page rejection run before the expensive model call.
    (4) Verifiable QA: per-page unit tests (table parses, math recompiles, reading order monotonic); failures retry with different sampling or escalate to a stronger model or human review.
    (5) Batch-First Serving: offline GPU batches with vLLM/SGLang; a tuned open pipeline processes a million pages for roughly $190, about 1/32 of frontier-API pricing.

    OCR pipeline: scanned pages enter preprocessing, then the single-pass document VLM, then per-page unit tests; passing pages go to structured storage, failing pages loop to retry or escalate to human review

    Figure 1: The pipeline: cheap normalization first, one VLM read per page, then machine-checkable tests decide whether the page ships, retries, or goes to a human.

    Clarify Before Designing:
    (1) Document Mix: born-digital PDFs versus degraded scans; which languages; is handwriting in scope?
    (2) Structure Fidelity: plain text, or RAG-grade structure with tables, equations, and reading order preserved?
    (3) Volume and Latency: nightly millions in batch, or interactive upload-and-wait in seconds?
    (4) Deployment Constraints: customer data residency or full self-hosting requirements (regulated archives)?
    (5) Downstream Contract: does the consumer want Markdown, or structured JSON field extraction (invoice totals, dates) on top?


    Login to view more content
  • MSD0015 LLM Request Routing

    Design the routing layer for an AI assistant that chooses, per request, between a small cheap model and a large expensive one. ChatGPT’s GPT-5 does exactly this with a real-time router that picks between its fast and reasoning variants, and research frameworks like RouteLLM show a trained router can cut serving cost by over 80% while holding about 95% of the strong model’s quality.

    How would you design this system? Cover what the router sees and how it is trained, how answer quality is guarded, the cost accounting, and how the system adapts as models are added, upgraded, or deprecated.

    Line-art scene: a stream of mixed user queries arriving at a toll gate that must choose between a cheap road and an expensive road, with a running cost meter and a question mark

    The Problem: most requests are easy, a few are hard, and sending everything to the biggest model burns money on “hello”. Design the gate that sends each request down the cheapest road that still answers it well.

    Answer

    The design is a trained per-request router: a tiny scorer reads the request and predicts the probability that the strong model’s answer beats the weak one’s, then sends the request to the cheapest model expected to clear the quality bar. This is routing, not cascading, so each request normally pays for exactly one model. The two pivotal decisions are to train the router on human preference data (which model’s answer people actually preferred, as in Chatbot Arena battles) rather than hand-built rules, and to expose an explicit cost-quality operating threshold as a product knob, with an escalation fallback so a routing mistake costs extra compute, not a bad answer.

    (1) Difficulty Signals: query embedding and length, task type, tool needs, and conversation state; the router is BERT-class or smaller, ~1/1000 the cost of a strong call.
    (2) Preference-Trained Router: learn P(strong model wins | query) from human preference battles, augmented with LLM-judged comparisons; route strong when P passes the threshold.
    (3) Explicit Operating Point: the threshold is chosen on the measured cost-quality curve and recalibrated as the traffic mix drifts.
    (4) Guarded Fallback: if the small model or a verifier flags low confidence, escalate to the large model; routing errors become cost, not bad answers.
    (5) Model Registry & Shadowing: candidates live behind a versioned registry; new models are shadow-scored on live traffic before the router is retrained or recalibrated.

    LLM routing pipeline: a request enters the router, which scores win probability and dispatches to the small or large model; a dashed escalation path runs from the small model through a confidence check to the large model, and user feedback loops back into router training

    Figure 1: The routing path: one cheap score per request, one paid model call, and an escalation hatch when the cheap path doubts itself.

    Clarify Before Designing:
    (1) Candidate Set: two models or many; closed APIs, self-hosted weights, or both; is the real split fast-versus-reasoning rather than small-versus-large?
    (2) Decision Granularity: per request, per message in a conversation, or pinned per session for style consistency?
    (3) Quality Bar: which evaluation defines “good enough” (human preference, task success), and how much loss versus the always-strong policy is tolerable?
    (4) Router Budget: how much latency and cost may the router itself add per request?
    (5) Traffic Shape: what fraction of traffic is trivial chat versus hard reasoning today, and how fast does that mix drift?


    Login to view more content
  • MSD0014 Music Identification

    Design a music identification system like Shazam: a user holds up a phone in a noisy cafe, records a 10-second snippet, and the app names the song within a second. Apple’s ShazamKit exposes the same matching to third-party apps, Google’s “Now Playing” identifies music continuously and offline on Pixel phones, and SoundHound even accepts hummed melodies.

    How would you design this system? Cover the audio fingerprint representation, the matching index, the latency and scale budget, and how the system behaves under noise, tempo changes, and remixes.

    Line-art scene: a cafe loudspeaker playing a song, a phone recording a short snippet through noise waves, and a question mark asking which song is playing

    The Problem: ten seconds of music buried in cafe noise must pick one recording out of tens of millions, in under a second, and a wrong answer is worse than none. Design the system that hears the song through the crowd.

    Answer

    The design is audio fingerprinting with landmark hashes, the approach Shazam published in 2003 and which remains the backbone of production matchers: convert audio to a spectrogram, keep only the strongest time-frequency peaks (a constellation map that survives noise), hash pairs of peaks into compact tokens, and match a query by finding reference tracks whose hashes recur with one consistent time offset. The two pivotal decisions are to match a lossy peak representation instead of the waveform (robustness to noise, codec compression, and reverb) and to use an inverted index over hashes with time-coherence voting, which turns “find this song” into a few hundred lookups and a histogram test rather than a comparison against the whole catalog.

    (1) Constellation Frontend: STFT spectrogram, keep local peaks only; noise must out-shout a peak to erase it, so ~20 peaks/second survive a cafe.
    (2) Combinatorial Hashing: each anchor peak pairs with peaks in a short target zone; the hash packs both frequencies and the time gap, giving millions of distinct tokens.
    (3) Inverted Index + Offset Voting: hash to list of (track, time) postings; matching query hashes vote on the offset, and a histogram spike declares the track.
    (4) Asymmetric Confidence: naming the wrong song costs more than “no match found”, so an answer needs enough aligned votes plus a margin over the runner-up.
    (5) Catalog Ingestion at Scale: new releases are fingerprinted as labels deliver them; the index is sharded by hash and held in RAM for sub-second queries.

    Music identification pipeline: a register lane fingerprints catalog tracks into a hash index, and a recognize lane turns a noisy snippet into hashes, votes on time offsets, and returns the track title

    Figure 1: Register and recognize lanes share one fingerprinting frontend; recognition is index lookups plus offset voting, never a comparison against raw audio.

    Clarify Before Designing:
    (1) Query Conditions: phone microphone in noise versus clean line-in audio, and how short a snippet must work (5 s? 15 s?)?
    (2) Catalog Scope: tens of millions of commercial tracks, and do covers, remixes, and live versions count as the same song?
    (3) Latency Budget: sub-second answer on a mobile connection, or is a few seconds acceptable?
    (4) On-Device versus Cloud: must matching run offline with a regional catalog subset (the Now Playing design), or is the phone always online?
    (5) Beyond Exact Recordings: is humming or cover identification in scope (a different, melody-based representation), or exact audio only?


    Login to view more content
  • MSD0013 Machine Translation at Scale

    Design a machine translation system for a product like Google Translate: text translation between 100+ language pairs, from high-resource pairs like English-Spanish down to low-resource languages with little parallel data, served interactively at web scale where users expect answers in a fraction of a second.

    How would you design this system? Cover the model architecture, how you get training data for low-resource languages, the serving design, and how you measure translation quality.

    Line-art scene: a grid of language nodes with dense cross edges illustrating the quadratic language-pair explosion, one document flowing in and translated copies flowing out, and a question mark over how to cover low-resource pairs

    The Problem: 100 languages mean roughly 10,000 directed pairs, most with almost no parallel data, and users still expect every pair to answer in milliseconds. Design one system that covers them all.

    Answer

    The design is a single massively multilingual encoder-decoder model trained on mined bitext plus back-translated monolingual text, with a target-language token steering generation (the NLLB recipe), behind a dual-track serving layer: a fast NMT track for short, latency-critical, terminology-sensitive text, and a fine-tuned translation LLM for long, nuanced, document-level input, which is exactly the split Google shipped in its Cloud Translation API (2024) and DeepL shipped as its next-gen model. The two pivotal decisions are the multilingual pooling (high-resource pairs teach low-resource ones through a shared representation, enabling zero-shot pairs) and the honest admission that one model family does not win everywhere: NMT still wins on latency, cost, and determinism, the LLM wins on context and fluency.

    (1) One Multilingual Model: shared encoder-decoder with a target-language token; transfer from high-resource pairs gives zero-shot coverage of unseen pairs instead of 10,000 separate models.
    (2) Data Flywheel: mine bitext from web crawls with multilingual sentence embeddings (LASER), then back-translate monolingual text to synthesize pairs for low-resource languages.
    (3) Dual-Track Serving: NMT for short/interactive/terminology-critical requests, translation LLM for long-form and idiomatic text; a router picks per request.
    (4) Quality Measurement: automatic metrics (COMET, BLEU) for regression, human MQM error marking for truth, A/B tests for product impact, all reported per language pair.
    (5) Low-Resource Strategy: zero-shot transfer first, then few-example adaptive conditioning (Google’s Adaptive Translation shows as few as 5, and up to 30k, example pairs can steer output at inference time).

    Translation architecture: source text enters a router that sends short interactive text to a fast NMT track and long nuanced text to a translation LLM track, both share multilingual training on mined bitext and back-translation, and outputs pass terminology constraints before serving

    Figure 1: Dual-track serving over one multilingual training base: the router sends short, latency-critical text to NMT and long, context-heavy text to the translation LLM; terminology constraints apply on both tracks.

    Clarify Before Designing:
    (1) Scope: text only, or also speech and image translation; and which language pairs at launch?
    (2) Latency Budget: interactive typing (sub-300 ms) versus document translation (seconds) imply different model families.
    (3) Quality Bar: gist-level understanding for users, or publication-grade output with human post-editing?
    (4) Terminology: must product names, legal terms, or brand glossaries be honored exactly?
    (5) Customization: do enterprise customers need domain adaptation (medical, legal) with their own example pairs?


    Login to view more content
  • MSD0012 Wake-Word Detection

    Design a wake-word detection system (e.g., Amazon’s “Alexa” or Apple’s “Hey Siri”) that spots a trigger phrase in a continuous audio stream on a phone or smart speaker. It must listen always-on without draining the battery, wake almost instantly when the user speaks, and almost never fire by mistake.

    How would you design this system? Cover the on-device architecture, the detection model, the training data, and how you measure accuracy.

    Line-art scene: a continuous audio waveform flowing into a smart speaker, one segment highlighted as the trigger phrase, a battery icon with a tight power budget, and a question mark over false alarms versus missed triggers

    The Problem: the detector discards nearly 100% of everything it hears, yet the one time it must fire, it has milliseconds and milliwatts to decide. Design the system that never sleeps but barely sips power.

    Answer

    The design is a two-stage cascade split across processors, the architecture Apple describes for its voice trigger system: a tiny streaming detector runs on the always-on low-power processor (DSP/AOP) tuned for high recall, and when it fires, a buffered audio segment goes to a larger, high-precision checker on the main application processor, optionally followed by speaker verification so only the enrolled user wakes the device. The two pivotal decisions are the cascade itself (the power budget makes one big always-on model impossible) and the operating point: false accepts are counted per unit of listening time (research reports them per hour of audio, products budget them per device-day) and they dominate the cost, so thresholds are tuned on an FA-versus-miss curve, not on accuracy.

    (1) Cascade Across Processors: stage 1 is a tiny quantized DNN on the always-on processor (high recall, permissive); stage 2 is a larger checker on the application processor (high precision) fed from a ring buffer.
    (2) Streaming Frontend: 16 kHz audio, 10 ms hops, log-mel filterbank frames, DNN posteriors over sub-word states, and a temporal integrator (HMM-style) that turns frame scores into one detection score.
    (3) Asymmetric Objective: false accepts per device-day is the headline metric; a second-chance threshold band briefly raises sensitivity after a near-miss instead of paying FA cost all the time.
    (4) Data Engine: real trigger recordings plus TTS-synthesized ones, augmented with noise, reverb, and far-field impulse responses, plus hard negatives (e.g., “seriously” for “Hey Siri”).
    (5) Privacy by Construction: no audio leaves the device before activation; personalization (speaker ID) runs on-device after enrollment.

    Wake-word cascade: microphone feeds a frontend and a tiny stage-one detector on the always-on processor, a ring buffer hands candidate audio to a larger stage-two checker on the application processor, then speaker verification, then the assistant activates

    Figure 1: The cascade: a high-recall listener on the low-power chip gates a high-precision checker on the main chip; a ring buffer carries the candidate audio across so no trigger onset is lost.

    Clarify Before Designing:
    (1) Device Class: phone, watch, or smart speaker; battery and DSP availability decide stage sizes (a watch gets ~5% of a tiny compute budget).
    (2) Trigger Spec: one phrase or several, fixed phrase or user-custom, and must it work hands-free in far-field rooms?
    (3) False-Accept Budget: how many accidental activations per day are tolerable, and what do they cost (battery, privacy review, user trust)?
    (4) Personalization: should only the enrolled owner’s voice trigger it, or anyone’s?
    (5) Cloud Role: may a cloud verifier re-check activations, or is the device fully offline?


    Login to view more content