
Explain the concept of “Sparsity” in neural networks.
Answer
Sparsity means that many of a network’s weights or activations are exactly zero. Sparse models are smaller to store, cheaper to run, and often more interpretable. It arises naturally (ReLU zeroes negative activations) or is induced deliberately through L1 regularization, pruning, or structured sparsity patterns designed for hardware acceleration.
(1) Weight Sparsity: Pruning or L1 drives unimportant weights to zero, so the model keeps accuracy with a fraction of its parameters.
(2) Activation Sparsity: ReLU produces zeros for all negative pre-activations, so only a subset of neurons “fire” per input.
(3) Hardware Payoff: Only structured sparsity (e.g., NVIDIA’s 2:4 pattern: 2 zeros in every 4 values) maps to real speedups; scattered zeros alone rarely accelerate dense GPU kernels.
Mathematical Formulation:


Where:
 is the -th model weight; the L1 penalty pushes small weights to exact zeros, with controlling sparsity strength.
- is a neuron’s pre-activation input; ReLU’s hard zero is the simplest source of activation sparsity.
 is the
 -th model weight; the L1 penalty pushes small weights to exact zeros, with
 controlling sparsity strength.
 is a neuron’s pre-activation input; ReLU’s hard zero is the simplest source of activation sparsity.
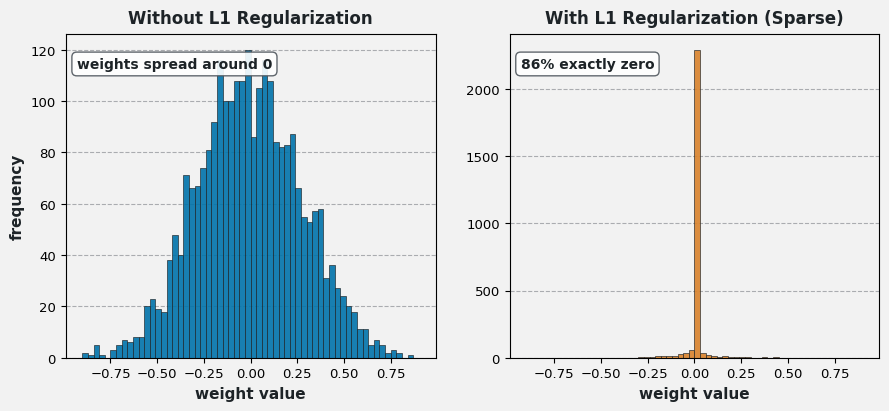
Figure 1: L1-induced weight sparsity: without L1 the weights form a broad bell; with L1 they collapse into a spike at exactly zero.
Hardware Support (NVIDIA 2:4): Since Ampere (A100) and continuing in Hopper/Blackwell, Sparse Tensor Cores require every block of 4 values to contain at least 2 zeros (50% structured sparsity); they then skip the zero multiplies, doubling effective GEMM throughput and roughly halving the stored weights plus memory bandwidth.
Leave a Reply