Author: admin

  • DL0090 Post-Training vs Quantization-Aware Training

    What is the difference between post-training quantization and quantization-aware training, and how would you choose between them when shipping a model to an on-device NPU?

    Answer

    Post-training quantization (PTQ) takes a finished float checkpoint and converts it to low precision after the fact: a few hundred unlabeled samples are pushed through the network so the tool can observe activation ranges, pick a scale and zero point per tensor or per channel, and round the weights. No labels, no loss, no backward pass, and typically minutes to a couple of hours on a single GPU. Quantization-aware training (QAT) instead inserts fake-quantization nodes into the graph and continues training, so every forward pass sees rounded values while gradients flow through the non-differentiable rounding step via the straight-through estimator (STE). The one-line distinction worth memorizing: PTQ fits the quantizer to fixed weights, while QAT moves the weights to fit the quantizer. At INT8 on a well-behaved network the two land within a few tenths of a point of each other, so PTQ wins on cost; at 4 bits and below, or on outlier-heavy and depthwise-separable models, PTQ falls off a cliff and QAT recovers most of the loss.

    (1) Where It Happens: PTQ is a post-processing step on a frozen checkpoint; QAT is a fine-tuning stage that must run inside your training pipeline with the original data loader and loss.
    (2) What Data It Needs: PTQ needs only a small calibration set (roughly 128 to 1024 unlabeled samples) that is representative of deployment traffic; QAT needs labeled data, or at least a teacher model for distillation.
    (3) The STE Trick: rounding has zero gradient almost everywhere, so QAT pretends the quantizer is the identity inside the clipping range and passes the gradient straight through, which is what lets weights drift toward values that round well.
    (4) Where PTQ Breaks: per-tensor scales collapse when channel ranges differ by orders of magnitude (depthwise convolutions), when activations carry massive outliers (transformer residual streams), or when the bit width drops to 4 or fewer.
    (5) Decision Rule: always try PTQ first because it is cheap and reversible; escalate to QAT only when a measured accuracy gap survives per-channel scales, better range selection, and bias correction.

    Mechanically, a fake-quant node applies quantize → dequantize in the forward pass, so tensors stay in float during QAT but carry exactly the values the integer kernel will produce at inference. That means QAT does not speed up training; it slows it down by 20 to 40 percent while simulating the deployment numerics. The payoff is that the optimizer sees the rounding error as part of the loss surface and settles into flatter minima where a few least significant bits do not matter. PTQ has no such feedback: whatever error the rounding introduces is simply propagated forward, which is why its failure mode is a sudden collapse rather than a graceful slide.

    Two horizontal pipelines. Top row, post-training quantization: trained FP32 checkpoint, calibration pass on 128 to 1024 unlabeled samples, fit scale and zero point, export INT model. Bottom row, quantization-aware training: trained FP32 checkpoint, insert fake-quant nodes, fine-tune with labels and STE gradients, fold scales and export INT model.

    Figure 1: The same checkpoint, two routes to integer inference. PTQ adds one forward-only calibration pass; QAT adds a full fine-tuning loop whose gradients reach the weights through the straight-through estimator.

    Mathematical Formulation:
    s = \frac{x_{max} - x_{min}}{2^{b} - 1}
    q = \mathrm{clip}(\lfloor x/s \rceil + z, 0, 2^{b} - 1)
    \hat{x} = s\,(q - z)
    \frac{\partial \mathcal{L}}{\partial x} \approx \frac{\partial \mathcal{L}}{\partial \hat{x}} \cdot \mathbf{1}[x_{min} \leq x \leq x_{max}]

    Where:

    • \hat{x} is the dequantized value the network actually computes with, and x is the original float weight or activation.
    • s is the scale and z the zero point (the integer that maps to exactly 0.0); q is the stored integer code.
    • b is the bit width, so b = 8 gives 256 levels and b = 4 only 16; x_{min}, x_{max} are the calibrated clipping bounds, chosen per channel for weights and per tensor or per token for activations.
    • \lfloor \cdot \rceil is round-to-nearest and \mathrm{clip} saturates values outside the representable range; both are the source of the error being managed.
    • The last line is the straight-through estimator: the indicator \mathbf{1}[\cdot] passes the gradient unchanged inside the clipping range and zeroes it outside, which is the only reason QAT can backpropagate through rounding.
    • PTQ solves for s, z with x held fixed; QAT keeps the whole chain in the graph and updates x (and, with learned-step methods, s itself).
    Line chart of top-1 accuracy versus bit width from INT8 down to INT2. PTQ tracks the FP32 baseline at INT8 and INT6 but drops to 68 at INT4, 41 at INT3 and 6 at INT2, while QAT stays at 74.5 at INT4, 71 at INT3 and 62 at INT2.

    Figure 2: Illustrative accuracy versus bit width. The two methods are indistinguishable at INT8, which is why PTQ dominates production INT8 pipelines; the gap opens abruptly at 4 bits and below, where the rounding error stops behaving like small additive noise.

    DimensionPost-Training QuantizationQuantization-Aware Training
    Data needed128 to 1024 unlabeled calibration samplesLabeled training data or a teacher for distillation
    ComputeMinutes to hours, one GPU, forward passes onlyHours to days, often multi-GPU, full training loop
    Pipeline accessWorks on a vendor or third-party checkpointRequires the original recipe, loss and hyperparameters
    Typical INT8 resultWithin roughly 0.5 points of FP32 with per-channel weightsEssentially lossless, rarely worth the cost
    Typical INT4 resultLarge drop unless advanced methods (GPTQ, AWQ) are usedRecovers most of the gap, the standard choice below 4 bits
    Iteration speedCheap to sweep many bit widths and granularitiesEach configuration is a separate training run

    Login to view more content
  • DL0089 RLHF: Human Feedback Training

    What is Reinforcement Learning from Human Feedback?

    Answer

    Reinforcement Learning from Human Feedback (RLHF) is a fine-tuning procedure that optimizes a language model against a learned model of human preferences instead of against a hand-written loss. It exists because the behaviors we actually want (helpful, honest, non-toxic, well-formatted answers) have no differentiable definition: next-token cross-entropy on scraped text rewards imitating the corpus, not satisfying a user. The standard recipe has three stages: supervised fine-tuning on demonstrations, training a reward model on human comparisons of pairs of responses, then optimizing the policy with an RL algorithm such as PPO against that reward, with a KL penalty pinning the policy near its starting point. Humans never grade individual tokens; they rank whole responses, and the reward model is the mechanism that turns those sparse rankings into a dense per-sequence training signal. InstructGPT is the canonical demonstration: labelers preferred outputs from the 1.3B InstructGPT model to those from the 175B pretrained GPT-3 base model despite roughly 100x fewer parameters, so the gain came from the objective rather than from scale.

    (1) Three-Stage Recipe: SFT → reward model → RL fine-tuning, where each stage consumes a different kind of human data (demonstrations, then comparisons, then only prompts).
    (2) Preferences Are Cheaper Than Demonstrations: asking “which of these two answers is better?” is faster and gives higher inter-annotator agreement than asking someone to write the ideal answer, and the Bradley-Terry model converts those binary comparisons into a scalar reward.
    (3) The KL Anchor Is Load-Bearing: the reward being optimized is a learned proxy, so the objective subtracts \beta times the KL divergence to the SFT reference policy; remove it and the policy walks off-distribution into text the reward model scores highly and humans hate.
    (4) Reward Hacking Is The Default Failure: proxy reward keeps rising while true human preference peaks and then declines, which is why production pipelines collect fresh comparisons on the current policy’s own samples rather than training once on a frozen dataset.

    Three-stage RLHF pipeline diagram: supervised fine-tuning on prompts plus demonstrations produces the reference policy, a reward model is trained on pairwise preference labels with the Bradley-Terry loss, and PPO optimizes the policy on prompts only against the frozen reward model minus a beta-weighted KL term, with a dashed path showing the SFT policy also serving as the KL anchor

    Figure 1: The three stages and the data each one needs. Stage 3 requires no new labels, only prompts, because the reward model has absorbed the human judgments, and the SFT checkpoint serves double duty as initialization and as the KL reference.

    The reward model is a copy of the transformer with the language-modeling head replaced by a scalar head, trained so that the preferred response scores higher than the rejected one. Because only differences of rewards appear in the loss, the reward scale and offset are unidentifiable, which is why RLHF implementations whiten or normalize rewards per batch before computing advantages. In stage 3 the policy samples completions for a prompt, the frozen reward model scores each one, and PPO takes a clipped policy-gradient step; the KL term is usually implemented as a per-token penalty folded into the reward rather than as a hard constraint. A naive PPO setup keeps four networks resident (policy, reference, reward model, value head), so memory and orchestration cost is the practical reason many teams reach for a direct preference method instead.

    Mathematical Formulation:
    \mathcal{L}_{RM} = -\log \sigma(r_\phi(x,y_w) - r_\phi(x,y_l))
    R(x,y) = r_\phi(x,y) - \beta \log \frac{\pi_\theta(y \mid x)}{\pi_{\mathrm{ref}}(y \mid x)}
    J(\theta) = \mathbb{E}_{x \sim \mathcal{D},\, y \sim \pi_\theta}[R(x,y)]

    Where:

    • \mathcal{L}_{RM} is the Bradley-Terry pairwise loss and \sigma is the logistic function, so the reward model is trained as a binary classifier over response pairs.
    • x is a prompt from the dataset \mathcal{D}, and y_w and y_l are the human-preferred and rejected responses to it.
    • r_\phi is the learned scalar reward model with parameters \phi; only reward differences are identified, so its absolute scale is arbitrary.
    • \pi_\theta is the policy being optimized and \pi_{\mathrm{ref}} is the frozen SFT policy; \beta > 0 sets how far the policy may drift, with typical values near 0.01 to 0.1.
    • R(x,y) is the KL-shaped reward actually fed to PPO, and J(\theta) is the on-policy objective, with the expectation taken over responses sampled from the current policy.
    Chart of reward versus KL divergence from the reference policy: the proxy reward model score rises monotonically with KL while the gold human preference score rises, peaks around 12 nats, and then declines, with a marker at the peak

    Figure 2: Illustrative overoptimization curve: the reward model score climbs without bound as the policy drifts, while measured human preference peaks and falls. \beta and early stopping exist to keep training left of that peak.

    AspectPPO-based RLHFDPOGRPO
    Separate reward modelYes, trained and frozenNo, the policy is its own implicit rewardYes, or a programmatic verifier
    SamplingOn-policy generation every stepOffline, fixed preference pairsOn-policy groups of responses per prompt
    Networks in memoryFour: policy, reference, reward, valueTwo: policy and referenceThree: no value network, group mean is the baseline
    Main failure modeReward hacking plus brittle PPO tuningStale data, drifts off the current policy distributionNoisy advantages when a whole group scores alike
    Best fitLarge budget, fresh labels, general helpfulnessFixed preference dataset, limited computeReasoning tasks with checkable answers

    Login to view more content
  • DL0088 PEFT: Parameter-Efficient Fine-Tuning

    Compare Parameter-Efficient Fine-Tuning (PEFT) methods: LoRA, adapters, and prompt/prefix tuning. When would you choose each?

    Answer

    All three families freeze the pretrained weights and train a tiny set of new parameters, but they differ in where those parameters live, and that single structural choice decides inference cost, serving flexibility, and achievable quality. LoRA adds a low-rank update in parallel to existing weight matrices, so after training the update folds back into W and costs exactly zero extra latency. Serial adapters insert a small bottleneck MLP inside the block’s forward path, which keeps task modules cleanly composable but adds depth, so every decoded token pays for them. Prefix and prompt tuning touch no weight matrix at all: prefix tuning prepends trainable key/value vectors at every layer, prompt tuning prepends trainable vectors only at the input embeddings, which is the cheapest option in parameter count but the least stable and it consumes context length. In practice LoRA is the default (paired with 4-bit quantization as QLoRA when GPU memory is the binding constraint), adapters win when modular composition matters more than latency, and prefix/prompt tuning wins when the base weights must stay byte-identical or when you want per-request conditioning.

    (1) Where The Parameters Live: LoRA sits parallel to chosen projections, adapters sit serially between sublayers, prefix tuning sits in the KV cache rather than in any weight tensor.
    (2) Mergeability Decides Latency: only LoRA is exactly mergeable into W_0; adapters add two matmuls and a nonlinearity per sublayer that cannot be folded away, which is a 10-25% decode overhead at batch 1 on a 7B model.
    (3) Capacity Is A Knob, Except For Prompts: rank r and bottleneck width b scale capacity smoothly, while prompt tuning’s capacity saturates and only becomes competitive with full fine-tuning above roughly 10B parameters.
    (4) Multi-Tenant Serving: unmerged LoRA and prefix tuning both support heterogeneous batching (per-request low-rank gather, or per-request KV prefix) from one frozen base copy; merged LoRA needs a separate weight copy per task and adapters need a weight swap per request.

    Diagram of one transformer block: input, LayerNorm, self-attention, LayerNorm, FFN, output. A blue LoRA box below attention taps the same input and adds its output back in parallel, a green prefix-tuning box above attention prepends trainable key and value vectors, and an orange serial adapter box sits in the path between the FFN and the block output

    Figure 1: The three injection sites in one block. LoRA is parallel and therefore mergeable, the adapter is serial and therefore always in the critical path (real adapter recipes place one after attention and one after the FFN), and prefix tuning changes only K and V, leaving every weight untouched.

    Two consequences are worth stating precisely because interviewers probe them. First, the merge is algebraically exact, not an approximation: W_0 + (\alpha/r)BA is just another matrix of the same shape, so a merged LoRA checkpoint is indistinguishable from a normally fine-tuned one at serving time, and the price is that you can no longer swap tasks without unmerging. Second, PEFT saves optimizer and gradient memory, not activation memory: with Adam you drop from roughly 12-16 bytes per trainable parameter of state to almost none, which is why a 7B model fine-tunes on a single 24GB card, but activations still scale with batch size and sequence length, and QLoRA’s 4-bit NF4 base plus paged optimizers is what pushes a 65B model onto one 48GB GPU. Prefix tuning has a third quirk: because the prefix occupies KV slots, a 20-token prefix at every layer permanently shortens the usable context and its quality is non-monotonic in prefix length, which is why the original work needed a reparameterization MLP to train stably at all.

    Mathematical Formulation:
    h = W_0 x + \frac{\alpha}{r} B A x
    W' = W_0 + \frac{\alpha}{r} B A
    h = x + W_{\mathrm{up}} \sigma(W_{\mathrm{down}} x)
    \tilde{K} = \mathrm{concat}(P_k, K)
    \tilde{V} = \mathrm{concat}(P_v, V)

    Where:

    • h is the sublayer output and x the input; W_0 is the frozen pretrained matrix of shape d_{out} \times d_{in}.
    • B \in \mathbb{R}^{d_{out} \times r} and A \in \mathbb{R}^{r \times d_{in}} are the LoRA factors with rank r \ll \min(d_{in}, d_{out}); A is Gaussian-initialized and B is zero-initialized so training starts from the pretrained function.
    • \alpha is a scaling constant, and the ratio \alpha/r keeps the effective update magnitude roughly stable when you sweep r; W' is the merged weight used at inference.
    • W_{\mathrm{down}} \in \mathbb{R}^{b \times d} and W_{\mathrm{up}} \in \mathbb{R}^{d \times b} form the adapter bottleneck of width b, with nonlinearity \sigma; the residual term x plus near-zero initialization makes the adapter an approximate identity at step 0.
    • P_k, P_v \in \mathbb{R}^{p \times d_k} are the per-layer, per-head prefix key and value vectors of length p; K, V are the ordinary projected keys and values, so attention runs over p + n positions for a sequence of length n.
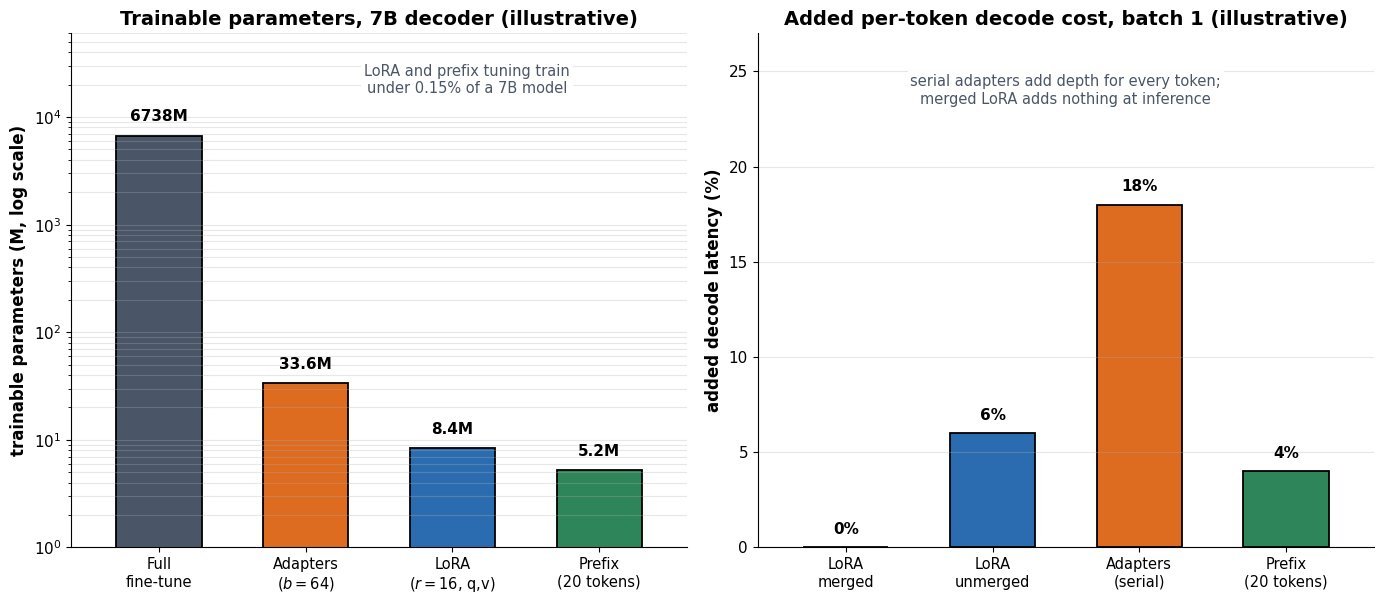
    Two-panel bar chart. Left panel, log scale: trainable parameters for full fine-tuning 6738M, adapters 33.6M, LoRA 8.4M, prefix tuning 5.2M. Right panel: added per-token decode latency at batch 1, merged LoRA 0 percent, unmerged LoRA 6 percent, serial adapters 18 percent, prefix tuning 4 percent

    Figure 2: Illustrative budgets for a 7B decoder with d = 4096 and 32 layers. Parameter counts span three orders of magnitude, yet the latency picture is unrelated to them: the smallest method is not the fastest, and merged LoRA is free.

    DimensionLoRASerial AdaptersPrefix / Prompt Tuning
    Insertion pointParallel to chosen linear layers (q,v by default; all attention and FFN projections for hard tasks)Serial bottleneck after the attention and FFN sublayersExtra K/V vectors at every layer (prompt tuning: input embeddings only)
    Trainable share (7B)0.05-0.5% (8.4M at r=16 on q,v)0.5-3% (33.6M at b=64, two per layer)Under 0.1% (5.2M for a 20-token prefix)
    MergeableYes, algebraically exactNo, extra depth is irreducibleNo, but no weight is modified either
    Inference cost0% merged; roughly 5-10% unmerged at batch 1Roughly 10-25% at batch 1, worst at small batchSmall KV cost, but the prefix permanently shortens usable context
    Many tasks, one baseStrong: keep unmerged and batch a per-request low-rank gatherWeak: needs a per-request module swap, though AdapterFusion composes trained modulesStrong: a prefix is just cached K/V, trivially per-request
    Quality on hard tasksMatches full fine-tuning closely at adequate rank; underfits at very low r on large domain shiftsComparable to LoRA, with a well-studied bottleneck-width knobLags on generation and reasoning; unstable below roughly 10B parameters
    Choose it whenDefault choice; memory-bound runs pair it with 4-bit QLoRA; hundreds of task variants over one baseYou want modular, composable, independently versioned task modules and have latency headroomBase weights must stay immutable, or you need cheap per-request conditioning at very large scale

    Login to view more content
  • DL0087 QLoRA: 4-bit Quantized LoRA

    What is QLoRA, and how does it combine 4-bit quantization with LoRA?

    Answer

    QLoRA (Dettmers et al., 2023) is a fine-tuning recipe that keeps the entire base model frozen in 4-bit precision and trains only LoRA adapters in 16-bit on top of it, so the memory that would have held gradients and optimizer state for billions of parameters simply never gets allocated. During the forward pass each 4-bit weight block is dequantized to bf16 on the fly, used for the matrix multiply, and discarded; the backward pass dequantizes again to propagate gradients through the frozen weights into the adapters, which are the only tensors that receive updates. Three components make the 4-bit base workable: the NF4 data type, which places its 16 levels at quantiles of a normal distribution rather than uniformly, double quantization of the per-block scaling constants, and paged optimizers that offload optimizer state through unified memory when a long-sequence step spikes. The headline result was fine-tuning a 65B model on a single 48 GB GPU while matching 16-bit LoRA quality on instruction-following benchmarks. Note that QLoRA quantizes the frozen base, never the adapters or the gradients, so all learning still happens in bf16.

    (1) NF4 (4-bit NormalFloat): pretrained weights within a block are approximately zero-centered Gaussian, so NF4 spaces its levels at quantiles of a standard normal instead of uniformly, which is information-theoretically optimal for that assumption and beats 4-bit float or int at equal bit width.
    (2) Blockwise Absmax Scaling: weights are quantized in blocks of 64 with one absmax constant per block, which localizes outliers so a single large weight cannot crush the resolution of an entire tensor.
    (3) Double Quantization: those constants are themselves quantized to 8-bit with a second-level fp32 scale per 256 constants, cutting the metadata overhead from 0.5 to about 0.127 bits per parameter (roughly 3 GB on a 65B model).
    (4) Only Adapters Train: gradients pass through the frozen 4-bit weights but are stored only for A and B, so optimizer state scales with the adapter rank, not with model size.
    (5) Paged Optimizers: optimizer states live in NVIDIA unified memory and are paged to host RAM during transient spikes, which is what keeps a 33B or 65B single-GPU run from OOM-ing on a long batch.

    Block diagram of a QLoRA linear layer: input X feeds a frozen NF4 base weight with its double-quantized absmax constants, which is dequantized to bf16 for the matmul, while a parallel bf16 LoRA A and B path scaled by alpha over r is added to produce output Y, with dashed gradient arrows returning only into A and B

    Figure 1: One QLoRA linear layer. The NF4 weight and its quantization constants are read-only, the bf16 copy exists only for the duration of the matmul, and the dashed path shows that gradients terminate at the low-rank adapters.

    Mathematical Formulation:
    Y = X\,\mathrm{dq}(W_4) + \frac{\alpha}{r}\,X A B
    \mathrm{dq}(W_4)_{ij} = c_i\,z_{q_{ij}}
    c_i = \mathrm{absmax}(W_i)
    b = 4 + \frac{8}{64} + \frac{32}{64 \cdot 256}
    b \approx 4.127\ \text{bits per parameter}

    Where:

    • Y is the layer output and X the bf16 input activation; both stay in 16-bit throughout.
    • W_4 is the frozen base weight stored as NF4 indices, and \mathrm{dq} is the dequantization that reconstructs a bf16 tile just before the matmul.
    • i indexes the blocks of 64 weights, q_{ij} \in \{0,\ldots,15\} is the stored 4-bit code, and z_k are the fixed NF4 levels, obtained from normal quantiles and rescaled to [-1, 1] with an exact zero.
    • c_i is the per-block absmax constant; double quantization stores it in 8 bits with one fp32 scale per 256 constants.
    • A \in \mathbb{R}^{d \times r} and B \in \mathbb{R}^{r \times k} are the trainable bf16 adapters of rank r (the paper uses r = 64 on every linear layer), scaled by \alpha / r; B starts at zero so the layer initially reproduces the quantized base model.
    • b is the effective storage cost per base parameter: 4 bits of payload plus 0.125 bits of 8-bit constants plus 0.002 bits of second-level scales.
    Horizontal stacked bar chart of training memory for a 7B model: full fine-tuning totals 112 GB with 14 GB weights, 14 GB gradients and 84 GB optimizer states; 16-bit LoRA totals 16.6 GB; QLoRA totals 6.2 GB with a 3.6 GB NF4 base

    Figure 2: Illustrative state memory for a 7B model with rank-64 adapters on all linear layers. LoRA removes the optimizer and gradient bulk, and QLoRA then shrinks the remaining frozen weights from 14 GB to 3.6 GB; activation memory is excluded.

    AspectQLoRA (NF4 base)16-bit LoRAFull Fine-Tuning
    Base weight storageNF4, about 4.13 bits per parameter with double quantizationbf16, 16 bits per parameterbf16 weights plus an fp32 master copy
    Trainable parameters (7B)About 160M in bf16 at rank 64 on all linear layersIdentical adapter countAll 7B parameters
    State memory (7B)About 6 GBAbout 17 GBAbout 112 GB, needs sharding across GPUs
    Step timeSlowest: dequantization runs in both forward and backwardFastest of the two adapter methodsHighest total compute and communication
    Instruction-tuning qualityMatches 16-bit LoRA when adapters cover every linear layerReference point for adapter tuningPreferred with very large in-domain corpora or heavy domain shift
    DeploymentAdapter cannot fold into NF4 losslessly; merge into the 16-bit base, then requantizeMerge into bf16 weights for zero added latencyOne merged checkpoint per task

    Login to view more content
  • DL0086 LoRA: Low-Rank Adaptation

    What is LoRA, and can you explain the low-rank decomposition idea and why it is parameter-efficient?

    Answer

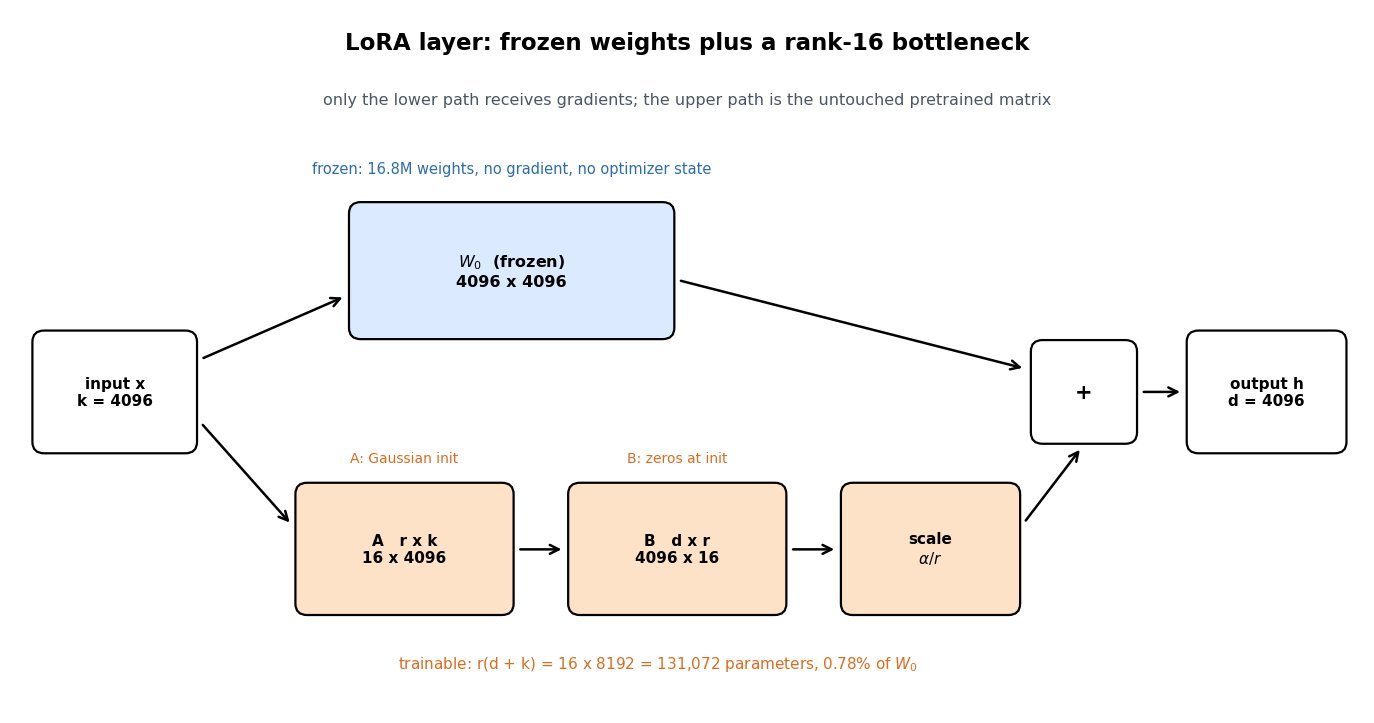
    LoRA (Low-Rank Adaptation) freezes every pretrained weight matrix and learns only a rank-constrained update beside it: instead of training W_0 + \Delta W with a full d \times k update, it factors the update as \Delta W = BA with B \in \mathbb{R}^{d \times r}, A \in \mathbb{R}^{r \times k} and r \ll \min(d,k). The motivation is the intrinsic-dimension hypothesis: adapting a large pretrained model to a downstream task moves the weights along a very low-dimensional subspace, so a rank-8 or rank-16 correction captures almost all of the useful change. For one 4096 \times 4096 attention projection, a rank-16 factorization trains 131,072 numbers instead of 16.8M, roughly 0.78% of the matrix. The efficiency that matters in practice is not forward FLOPs, which barely change, but optimizer and gradient state: Adam keeps two moments plus an fp32 master copy per trainable parameter, so shrinking the trainable set by two or three orders of magnitude is what turns a multi-node job into a single-GPU job. At inference the product can be folded back with W' = W_0 + (\alpha/r)BA, so a merged LoRA adds zero latency compared with the original model.

    (1) Frozen Base, Additive Branch: the pretrained matrix never receives a gradient; all learning happens in the parallel BA branch whose output is added to the frozen path.
    (2) Rank Is The Budget Knob: parameter count is r(d+k) and grows linearly in r, while the full matrix costs dk, so the ratio is tiny for any practical rank.
    (3) Zero Initialization On One Factor: A gets a random Gaussian init and B is initialized to zeros, so \Delta W = 0 at step 0 and training starts exactly at the pretrained function.
    (4) Memory Savings Come From Optimizer State: gradients and Adam moments exist only for adapter parameters, which is where the 8x reduction in peak training memory comes from, not from cheaper matrix multiplies.
    (5) Mergeable And Swappable: a task adapter is a few tens of MB, so many tasks can share one frozen base, either merged per deployment or batched as separate adapters in a single server.

    Diagram of a LoRA layer: the input feeds a frozen 4096 by 4096 projection on the upper path and a rank-16 bottleneck A then B then alpha over r scaling on the lower path, with both paths summed into the output

    Figure 1: A LoRA layer keeps the frozen 16.8M-parameter projection untouched and routes the input through a rank-16 bottleneck whose 131,072 trainable parameters are added back, scaled by \alpha/r.

    Two implementation details do most of the work. The scaling factor \alpha/r decouples the effective update magnitude from the rank, so raising r to add capacity does not silently multiply the learning rate on the adapter branch; the common convention is to fix \alpha and sweep r. The choice of target modules matters more than the rank in most experiments: the original paper adapted only the attention query and value projections, while current practice applies LoRA to all linear layers including the MLP, which raises trainable parameters to about 42M on an 8B model but consistently closes the gap to full fine-tuning. One caveat on merging: if the base weights are quantized, folding a bf16 adapter into a 4-bit matrix reintroduces quantization error, so quantized deployments usually keep the adapter separate.

    Mathematical Formulation:
    h = W_0 x + \Delta W x
    \Delta W = \frac{\alpha}{r} B A
    |\Theta| = r(d + k)
    \rho = \frac{r(d + k)}{d k}
    W' = W_0 + \frac{\alpha}{r} B A

    Where:

    • h is the layer output and x \in \mathbb{R}^{k} the input activation for one token.
    • W_0 \in \mathbb{R}^{d \times k} is the frozen pretrained matrix, and \Delta W is the learned correction.
    • B \in \mathbb{R}^{d \times r} and A \in \mathbb{R}^{r \times k} are the trainable factors; the rank r satisfies r \ll \min(d,k), which forces \mathrm{rank}(\Delta W) \leq r.
    • \alpha is a fixed scaling constant, so \alpha/r keeps the update magnitude roughly rank-independent.
    • |\Theta| is the trainable count per adapted matrix and \rho its fraction of the full matrix; with d = k = 4096 and r = 16 this gives 131,072 parameters and \rho \approx 0.0078.
    • Required initial condition: B = 0 with A Gaussian, so \Delta W = 0 before the first step; the last line is the merge applied after training.
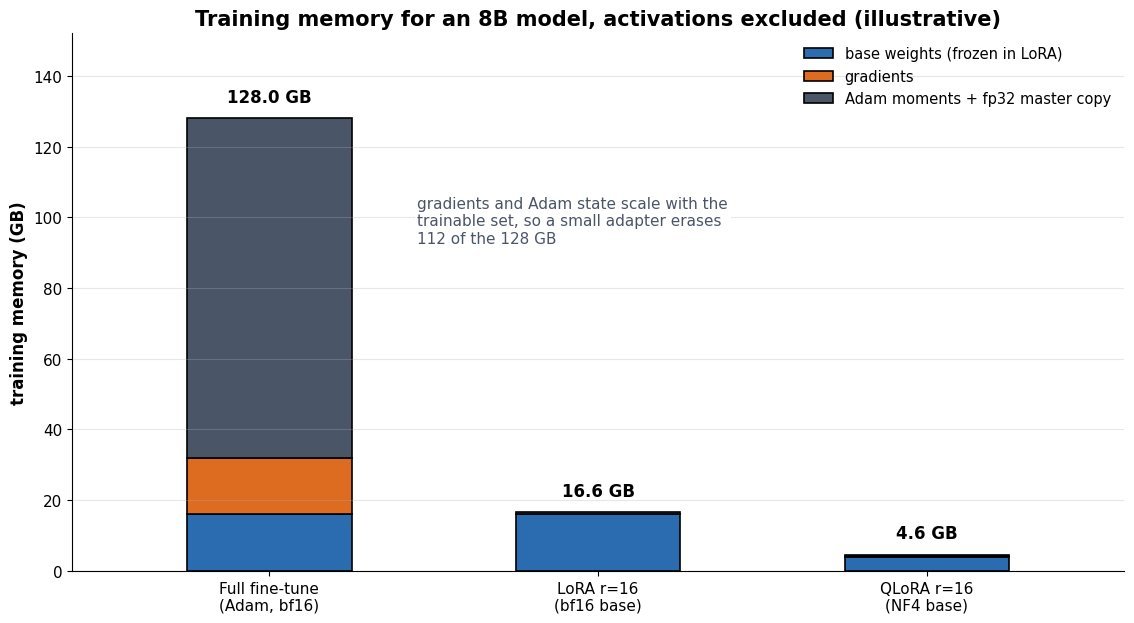
    Stacked bar chart of training memory in gigabytes for an 8B model: full fine-tuning totals 128 GB from 16 GB base weights, 16 GB gradients and 96 GB optimizer state, LoRA rank 16 totals 16.6 GB, and QLoRA with a 4-bit base totals 4.6 GB

    Figure 2: Illustrative training memory for an 8B model before activations: full fine-tuning spends 96 GB on Adam state alone, LoRA with 41.9M trainable parameters needs about 16.6 GB, and a 4-bit frozen base drops that to about 4.6 GB.

    PropertyLoRAFull Fine-TuningBottleneck Adapters
    Trainable parameters (8B model)41.9M at r=16 on all linear layers, about 0.5%8.0B, all of themComparable order, set by bottleneck width
    Added inference latencyNone once merged into the base weightsNoneExtra sequential layers, noticeable at small batch
    Peak training memoryAbout 17 GB, or 5 GB with a 4-bit baseAbout 128 GB with Adam in mixed precisionSimilar to LoRA
    Multi-task servingHundreds of small adapters over one frozen base, batchableOne 16 GB checkpoint per taskSwappable but cannot be merged away
    Quality ceilingMatches full tuning on most instruction and style adaptationUpper bound, clearly better for large domain shiftRoughly on par, less used today

    Login to view more content
  • DL0085 RAG vs Fine-Tuning

    When should you use RAG instead of fine-tuning?

    Answer

    Reach for RAG when the failure is a knowledge gap, and fine-tune when the failure is a behavior gap. Knowledge gaps look like this: the required facts change (pricing, inventory, incident history), they are private to a tenant, they are too numerous to memorize (millions of documents), or the answer must carry a citation a human can audit. Behavior gaps look different: the model has the right context in the prompt and still emits the wrong JSON schema, the wrong tone, the wrong clinical or legal register, or a malformed tool call. The diagnostic that settles most arguments is a context-injection test: paste the gold document into the prompt by hand, and if the answer becomes correct, you have a retrieval problem, not a weights problem. Update economics reinforce the split, because a corrected fact ships to a RAG system in minutes by reindexing one chunk, while the same correction in a fine-tuned checkpoint means a training run plus a full regression eval, and controlled comparisons have repeatedly found that continued pretraining on new documents injects facts less reliably than simply retrieving them.

    (1) Knowledge vs Behavior Test: if hand-pasting the gold document fixes the output, choose retrieval; if the model still misbehaves with perfect context, the deficit is in the weights and only fine-tuning (or better prompting) moves it.
    (2) Update Latency And Provenance: RAG updates at index write speed and can return source spans for audit, whereas a fine-tuned model has no pointer back to evidence and its knowledge is frozen at the last training run.
    (3) Cost Moves From Training To Serving: retrieval adds a lookup plus k \cdot n_{chunk} prefill tokens on every query, while fine-tuning pays once up front and then serves short prompts, which matters under a tight token budget or a strict p99 latency SLO.
    (4) Failure Modes Are Different: RAG fails by retrieval miss or by grounding on a plausible distractor chunk; fine-tuning fails by confidently asserting stale facts and by catastrophic forgetting of general ability.
    (5) The Honest Answer Is Often Both: use RAG for the facts and a small LoRA adapter for format, jargon, and the skill of reading retrieved context (including ignoring irrelevant chunks), which is what retrieval-aware fine-tuning trains explicitly.

    Flowchart: a failure measured on a held-out eval set fans out into three branches, knowledge gap, behavior gap, and both gaps, which route to RAG updated by reindexing, a LoRA fine-tune updated by retraining, and retrieval-aware fine-tuning that runs both pipelines, with per-query cost notes beneath each option

    Figure 1: The decision starts from a measured failure, not from a technology preference: classify the gap first, then accept the update path and per-query cost that come with the chosen option.

    The serving arithmetic is worth doing before committing. A 60-token question with k = 5 retrieved chunks of 400 tokens each becomes a 2060-token prefill, roughly 34 times the baseline prompt, plus 20 to 80 ms of vector search and reranking. That is usually cheaper than a training run, but it is a recurring per-request tax, and it is why teams with a small static corpus sometimes skip retrieval entirely and rely on long context with prompt caching. Fine-tuning inverts the profile: one-off data curation and GPU hours, then thin prompts forever. A common production shape is retrieve → rerank → generate on a live index, with a LoRA adapter handling the output contract, so the two mechanisms address the two gaps independently instead of competing.

    Mathematical Formulation:
    p(y \mid x) = \sum_{z \in \mathcal{Z}_k} p_{\eta}(z \mid x) p_{\theta}(y \mid x, z)
    \theta^{*} = \arg\min_{\theta} \mathcal{L}(\theta; \mathcal{D}_{ft})
    n_{prefill} = n_{q} + k \cdot n_{chunk}
    t_{total} = t_{retrieve} + t_{prefill} + t_{decode}

    Where:

    • y is the generated answer and x the user query; the first line is the RAG marginalization, where new knowledge enters through the retrieved set rather than through the weights.
    • z is a retrieved passage from the top-k set \mathcal{Z}_k, scored by the retriever p_{\eta}, and p_{\theta} is the generator; only \mathcal{Z}_k changes when you reindex.
    • \theta^{*} is the fine-tuned parameter set obtained by minimizing loss \mathcal{L} on the curated set \mathcal{D}_{ft}; with LoRA only a low-rank delta is trained, so \theta itself stays frozen.
    • n_{q} is the question length, n_{chunk} the tokens per chunk, and n_{prefill} the per-query context the RAG path must pay for; fine-tuning leaves n_{prefill} = n_{q}.
    • t_{retrieve}, t_{prefill} and t_{decode} are the latency terms; a hard SLO such as t_{total} \leq 300 ms with k = 20 chunks is where retrieval budgets usually break.
    Line chart of fact-level answer accuracy over 365 days after a training cutoff: a fine-tuned checkpoint with no retraining decays from 0.88 to about 0.30, quarterly retraining produces a sawtooth that recovers to 0.88 every 91 days, and RAG over a live index stays flat near 0.86

    Figure 2: Illustrative fact churn of about 15 accuracy points per quarter: a frozen fine-tuned checkpoint decays, quarterly retraining buys a sawtooth that is stale by construction between runs, and a live index holds accuracy flat with no training at all.

    DimensionRAGFine-TuningBoth
    Best forChanging, private, or high-volume facts that need citationsOutput format, tone, domain jargon, tool-call syntax, latency cutsGrounded answers in a strict contract, with noisy retrieval
    Update pathReindex the changed chunk, minutes, no GPUNew data, training run, regression eval, redeployReindex for facts, retrain only when behavior shifts
    ProvenanceSource spans returned with the answerNone; knowledge is diffuse in weightsSame as RAG, with better citation discipline
    Per-query costRetrieval latency plus k \cdot n_{chunk} prefill tokensShort prompt only; cheapest at high QPSSame as RAG, plus adapter serving
    Main failure modeRetrieval miss, distractor chunks, lost-in-the-middleStale confident facts, catastrophic forgetting, overfit styleTwo systems to version, debug, and evaluate together
    Build effortChunking, embeddings, index, reranker, eval setLabeled pairs, hyperparameters, GPU time, eval harnessHighest, so justify it with measured gains over RAG alone

    Login to view more content
  • DL0084 RAG: Retrieval-Augmented Generation

    What is RAG (retrieval-augmented generation), and describe the components of a RAG pipeline?

    Answer

    Retrieval-augmented generation conditions a frozen language model on text fetched at query time from an external corpus, so the answer is grounded in documents the model never memorized. Nothing about the weights changes: the retriever supplies evidence, the prompt carries it, and the decoder writes an answer that should be traceable to that evidence. This buys three things a fine-tuned model cannot easily give you, namely freshness (reindex a document and the next query sees it), attribution (each claim can cite a chunk ID), and access control (metadata filters keep a user out of documents they may not read). A practical pipeline has an offline half and an online half: the offline half runs chunk → embed → index, and the online half runs retrieve → rerank → assemble prompt → generate. The parts that decide whether the system works in production are rarely the LLM; they are the chunking policy, the hybrid retrieval that combines dense and lexical matching, and the cross-encoder reranker that decides which five of fifty candidates actually reach the context window.

    (1) Ingestion and Chunking: parse the source into text, then split it into passages of roughly 400 to 800 tokens with modest overlap, attaching metadata (document ID, section, timestamp, ACL tags) that later powers filtering and citation.
    (2) Embedding and Indexing: a bi-encoder maps each chunk to a fixed vector stored in an ANN index (HNSW or IVF-PQ) alongside a sparse BM25 or SPLADE index, because dense and lexical retrieval fail on different queries.
    (3) Query Processing and Retrieval: the query is optionally rewritten (decontextualized against chat history, expanded, or decomposed for multi-hop), encoded once, and used to pull a wide candidate set of 30 to 100 chunks from both indexes, fused by reciprocal rank fusion.
    (4) Reranking and Context Assembly: a cross-encoder scores each query-chunk pair jointly and keeps the top 3 to 8, which are deduplicated, ordered, and packed into the prompt with instructions to answer only from the provided context and to cite chunk IDs.
    (5) Generation, Evaluation, and Guardrails: the LLM generates a grounded answer, and an offline harness tracks retrieval recall@k separately from answer faithfulness, since a wrong answer with perfect retrieval and a right answer with broken retrieval demand opposite fixes.

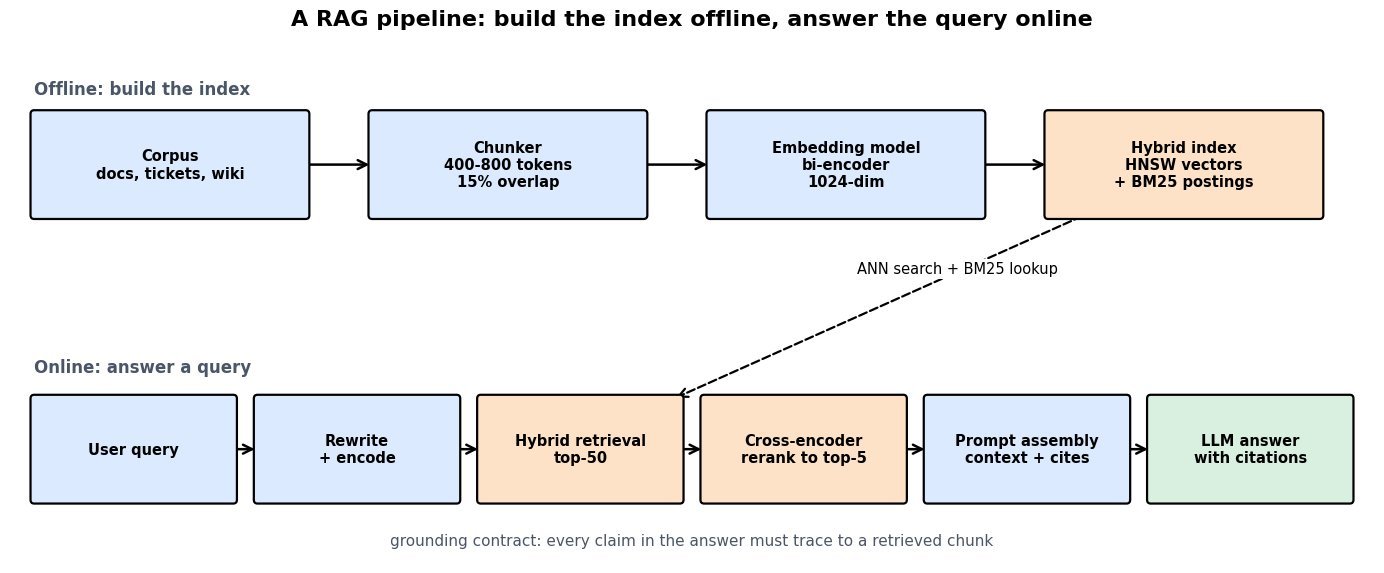
    Two-row diagram: the offline row runs corpus to chunker to embedding model to a hybrid index of HNSW vectors plus BM25 postings; the online row runs user query to rewrite and encode to hybrid retrieval of top-50 candidates to a cross-encoder rerank to top-5 to prompt assembly to LLM answer with citations, with a dashed arrow from the index down to the retrieval stage

    Figure 1: The offline half builds a hybrid index once per document revision; the online half spends its latency budget on retrieval, reranking, and decoding, and only the reranked top-5 chunks ever enter the context window.

    Most RAG failures are retrieval failures, so it helps to measure each stage separately. A useful decomposition is recall@50 for the first-stage retriever (did the answer-bearing chunk survive at all?) and recall@5 after reranking (did it reach the prompt?). Dense bi-encoders miss exact identifiers such as error codes, part numbers, and rare acronyms, which BM25 handles trivially; BM25 misses paraphrases, which the bi-encoder handles. Fusing the two lists and then letting a cross-encoder read query and chunk together typically removes a large share of the remaining misses, at the cost of one extra model call over 50 pairs, which is why the reranker runs on the shortlist and never on the corpus.

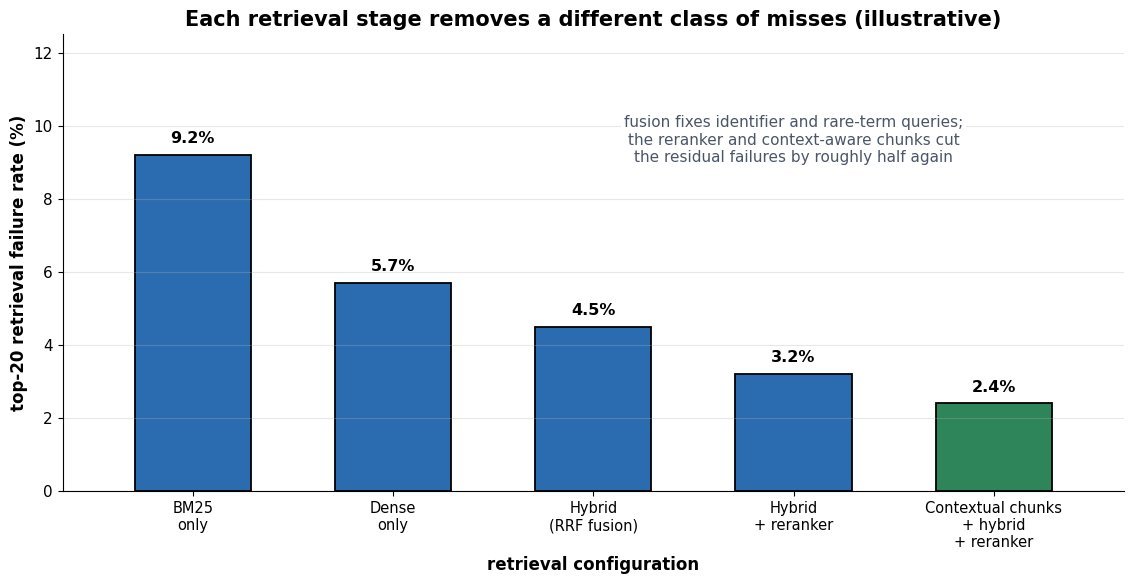
    Bar chart of top-20 retrieval failure rate for five configurations: BM25 only at 9.2 percent, dense only at 5.7 percent, hybrid fusion at 4.5 percent, hybrid plus reranker at 3.2 percent, and contextual chunk embeddings plus hybrid plus reranker at 2.4 percent

    Figure 2: Illustrative stage-by-stage gains: hybrid fusion fixes the queries dense retrieval alone drops, and the cross-encoder reranker plus context-aware chunk embeddings cut the residual failure rate further.

    Mathematical Formulation:
    s(q,c) = \frac{e_q^{\top} e_c}{\|e_q\|\,\|e_c\|}
    \mathcal{R}_k(q) = \text{top-}k\{\, s(q,c) : c \in \mathcal{D} \,\}
    \mathrm{RRF}(c) = \sum_{r=1}^{R} \frac{1}{K + \mathrm{rank}_r(c)}
    p(y \mid q) = \prod_{t=1}^{T} p_\theta(y_t \mid y_{1:t-1}, q, \mathcal{R}_k(q))

    Where:

    • s(q,c) is the cosine similarity between the query embedding e_q and the chunk embedding e_c, both produced by the same bi-encoder.
    • \mathcal{D} = \{c_1,\ldots,c_M\} is the chunked corpus with M passages, and \mathcal{R}_k(q) is the retrieved set of size k that the prompt will carry.
    • \mathrm{RRF}(c) fuses R ranked lists (dense, lexical, and any filtered variants); \mathrm{rank}_r(c) is the position of chunk c in list r, and the constant K \approx 60 damps the influence of top ranks so one confident list cannot dominate.
    • p_\theta is the frozen decoder, y_t the token at step t of a T-token answer; the retrieved set enters only as prompt context, so \theta is never updated by indexing new documents.
    • In practice the ANN index returns an approximate \mathcal{R}_k: HNSW recall is tuned by the search-width parameter, and quantized indexes trade a small recall loss for roughly 4\times to 8\times less memory.
    DimensionRAGFine-tuningLong-Context Stuffing
    Best forLarge, changing, permissioned corporaStyle, format, task behavior, domain jargonSmall corpora that fit in one window
    Update costReindex the changed chunks, secondsA new training run per refreshNone, but every request pays for the tokens
    AttributionNative: cite the retrieved chunk IDNone, facts are diffused into weightsPossible, but no ranking signal to audit
    Main failure modeRetriever misses the answer-bearing chunkConfident stale answers, catastrophic forgettingLost-in-the-middle, cost and latency growth
    Serving complexityHigh: index, retriever, reranker, eval harnessLow at serve time, high at train timeLow, especially with prompt caching

    Login to view more content
  • DL0083 LLM Hallucination and Reduction

    What is hallucination in LLMs, and what techniques reduce it?

    Answer

    A hallucination is fluent, confident model output that is not supported by the provided source or by verifiable fact. The standard split is intrinsic (the output contradicts a document that was placed in the context) versus extrinsic (the output adds unsupported content, such as an invented citation, API argument, or date). Hallucination is structural rather than a bug in any single checkpoint: next-token maximum likelihood rewards plausible continuations, not true ones, parametric memory of rare facts is lossy, and benchmarks scored on plain accuracy give zero credit for saying “I don’t know,” so a guess strictly dominates an abstention during both evaluation and preference tuning. Reduction therefore works on three fronts at once: put the evidence in the context (retrieval grounding with citations), check the produced claims against that evidence (claim-level verification), and change the objective so the model is allowed to abstain when its confidence is below the scoring threshold.

    (1) Grounding Beats Recall: retrieving the passage and requiring an inline citation converts a memory problem into a reading-comprehension problem, which is what cuts unsupported claims the most for factual queries.
    (2) Verify At Claim Granularity: decompose the answer into atomic claims and run an entailment (NLI) check of each claim against its cited span; a single unsupported claim in an otherwise correct paragraph is exactly what whole-answer scoring misses.
    (3) Uncertainty Signals: sampling several answers and measuring disagreement over meanings rather than token strings (semantic entropy, SelfCheckGPT-style consistency checks) flags confabulation without any external corpus.
    (4) Calibrated Abstention: a fixed answer-or-abstain threshold derived from the scoring rule trades coverage for precision, and is the only technique that removes hallucinations the retriever never had evidence for.
    (5) Decoding And Tuning Help At The Margin: contrastive decoding against earlier layers or against the ungrounded prior, plus fine-tuning that rewards “insufficient evidence” responses, reduce sycophancy and copy-drift but do not manufacture missing knowledge.

    Grouped bar chart comparing hallucination rate and answer coverage for five configurations: closed-book baseline at 42 percent hallucination and 100 percent coverage, chain of thought with self-consistency at 31 and 100, RAG top-5 at 18 and 98, RAG plus claim verification at 11 and 95, and RAG plus verification plus abstention at 4 percent hallucination but only 78 percent coverage

    Figure 1: Illustrative long-tail QA sweep: grounding and verification push the hallucination rate from 42% to 11% while coverage stays near 95%, and only abstention reaches 4%, at the cost of dropping coverage to 78%.

    In production the pieces are wired as one loop rather than as independent tricks: retrieve → generate with citations → extract claims → entail each claim against its cited span, and route anything unsupported to a second retrieval pass or to an explicit refusal. Two details decide whether the loop actually helps. First, the verifier must judge support, not plausibility, so an NLI model or a judge restricted to the cited span is required; asking the same generator “is this correct?” mostly reproduces its original error. Second, a retrieval miss must be visible: if the top-k passages are off-topic and the prompt still demands an answer, the model quietly falls back to parametric memory and attaches a real-looking citation to a fabricated statement, which is the worst failure mode because it survives casual review. Systems that expose this path well (Google’s Vertex AI grounding returns per-claim support scores alongside the answer) make the unsupported fraction a monitorable metric instead of an anecdote.

    Left to right pipeline of six boxes: user query, retrieve top-k passages, generate answer with citations, split into atomic claims, NLI check versus cited passage, return answer plus evidence, with a dashed feedback path from the NLI check back to the retriever labelled unsupported claim, re-retrieve or abstain

    Figure 2: The verification loop: every atomic claim is entailment-checked against the span it cites, and unsupported claims trigger re-retrieval or abstention instead of being returned with a decorative citation.

    Mathematical Formulation:
    \mathbb{E}[S] = p - c\,(1 - p)
    p \geq \frac{c}{1 + c}
    p(C_k \mid x) = \sum_{s \in C_k} p(s \mid x)
    H_{sem}(x) = -\sum_{k=1}^{K} p(C_k \mid x)\,\log p(C_k \mid x)

    Where:

    • \mathbb{E}[S] is the expected score of answering under a rule that pays +1 for correct, -c for wrong, and 0 for abstaining; p is the model’s probability that its answer is correct.
    • The second line is the abstention threshold: answer only when p clears it. Plain accuracy scoring is the case c = 0, where the threshold collapses to 0 and guessing is never penalized, which is the incentive that trains hallucination into the model.
    • x is the prompt and s a sampled generation; C_k is a semantic equivalence class of generations grouped by bidirectional entailment, with k \in \{1,\ldots,K\} indexing the K distinct meanings observed.
    • H_{sem}(x) is the semantic entropy: it is near 0 when all samples paraphrase one meaning and large when the model spreads mass over mutually contradictory meanings, so a high value is a practical confabulation flag even when token-level entropy is low.
    TechniqueWhat It Actually FixesCostWhen to Reach for It
    Retrieval grounding with citationsMissing or stale parametric knowledge; long-tail entitiesIndex build plus retrieval latency and a much longer promptDefault for any factual, enterprise, or time-sensitive query
    Claim extraction plus NLI verifierAnswers that cite a real source but overstate what it saysOne extra model call per claim; adds hundreds of msRegulated or high-stakes surfaces where citations are shown to users
    Sampling self-checks and semantic entropyConfabulation on questions with no retrievable source5x to 20x tokens; misses confident systematic errorsOffline audits, dataset cleaning, and routing to human review
    Calibrated abstention and refusal tuningGuessing when evidence is absent; sycophantic agreementLower coverage and more “I cannot verify this” responsesWhen a wrong answer costs far more than a missing one
    Contrastive decoding (DoLa, context-aware)Drift back to the parametric prior while a document is in contextCheap, but needs logit access and per-model tuningSummarization and closed-context QA on self-hosted models

    Login to view more content
  • DL0082 LLM Temperature

    What is LLM temperature?

    Answer

    Temperature is a single positive scalar that divides the model’s logits before the softmax at every decoding step, so it reshapes the next-token distribution without touching the model weights. At T = 1 you sample from exactly the distribution the model was trained to produce; values below 1 sharpen that distribution toward the highest-scoring token, and values above 1 flatten it toward uniform over the vocabulary. The transformation is monotone in the logits, so temperature never changes which token is ranked first, only how much probability the gaps between logits are worth. The practical effect is a variance knob: low temperature gives repetitive but stable text, high temperature gives diverse text with a much fatter tail of implausible tokens. Because it is applied independently at every step of an autoregressive loop, a small per-token change in tail mass compounds across a long generation.

    (1) Logit Rescaling, Not Reranking: dividing all logits by the same T preserves their order, so the argmax token is invariant and only the sampling probabilities move.
    (2) The Two Limits: as T approaches 0 sampling collapses to greedy decoding, and as T grows the distribution approaches uniform; frameworks special-case T = 0 as argmax because the division itself is undefined.
    (3) Tails Gain Disproportionately: temperature is a power transform of the base distribution, so unlikely tokens change by the largest relative factor; with logits (4, 3, 2, 1) the top token falls from 0.644 to 0.455 at T = 2 while the weakest rises from 0.032 to 0.102.
    (4) Compounding Across Steps: the model conditions on its own samples, so one low-quality token drawn from the inflated tail can steer every subsequent token, which is why high temperature degrades long generations faster than short ones.
    (5) Not A Truthfulness Knob: lowering T reduces variance, not error; if the mode is wrong, greedy decoding returns the wrong answer with total confidence.

    Grouped bar chart of next-token probabilities for four tokens with logits 4.0, 3.0, 2.0 and 1.0 at temperatures 0.5, 1.0 and 2.0, showing the top token falling from 0.865 to 0.455 and the weakest token rising from 0.002 to 0.102

    Figure 1: The same four logits under three temperatures. Entropy grows from 0.66 bits at T = 0.5 to 1.80 bits at T = 2, and the weakest token gains roughly 47x probability across that range while the top token loses less than half.

    Temperature never acts alone in a real decoder. The usual pipeline is logits → temperature → top-k or top-p truncation → renormalize → sample, and the ordering matters: because temperature runs first, raising it inflates the tail that nucleus sampling then has to cut, so the same p = 0.95 threshold admits a larger candidate set than it did at T = 1. That is why “high temperature plus top-p” is not a safety net, and why many production defaults pair a moderate temperature with a fixed truncation instead of pushing either one hard. A separate but easily confused use of the same formula is temperature scaling for calibration, where a single T is fit on held-out data to correct an overconfident classifier; there the goal is matching predicted confidence to observed accuracy, not generating diverse text, and the fitted value is a property of the model rather than a user-facing creativity dial.

    Mathematical Formulation:
    p_i(T) = \frac{\exp(z_i/T)}{\sum_{j=1}^{V} \exp(z_j/T)}
    p_i(T) \propto p_i(1)^{1/T}
    i^{*} = \arg\max_j z_j
    \lim_{T \to 0^{+}} p_{i^{*}}(T) = 1
    H(T) = -\sum_{i=1}^{V} p_i(T) \log_2 p_i(T)

    Where:

    • p_i(T) is the sampling probability of vocabulary token i at temperature T, and z_i is that token’s raw logit from the final linear layer.
    • V is the vocabulary size and j indexes every candidate in the softmax denominator, so all probabilities are renormalized after rescaling.
    • T > 0 is the temperature: values below 1 sharpen the distribution, values above 1 flatten it, and T = 1 is an identity operation.
    • The second line shows temperature is a power transform with exponent 1/T applied to the base distribution, which is the compact reason tail tokens move by the largest relative factor.
    • i^{*} is the argmax token, and the fourth line is the greedy limit; implementations therefore branch to argmax at T = 0 instead of evaluating the ratio.
    • H(T) is the entropy of the next-token distribution in bits; it increases monotonically with T and is bounded above by \log_2 V.
    Two panels versus temperature from 0.05 to 5: left panel shows entropy in bits rising monotonically from near 0 toward the 2-bit uniform limit and passing 1.37 bits at T equals 1; right panel shows top-token probability falling from 1 to about 0.33 while the mass of the two weakest tokens rises from near 0 to about 0.40

    Figure 2: Sweeping T over the same four logits. Entropy is monotonically increasing and saturates at \log_2 4 = 2 bits, while the tail mass of the two weakest tokens more than doubles between T = 1 and T = 2.

    KnobTemperatureTop-kTop-p (Nucleus)
    What it changesRescales all logits; every token keeps nonzero probabilityKeeps the k highest-scoring tokens, zeroes the restKeeps the smallest set whose mass reaches p, zeroes the rest
    Adapts to context?No, the same scalar at every step regardless of confidenceNo, a fixed candidate countYes, the set shrinks when the model is confident
    Typical failure modeToo low: loops and boilerplate. Too high: off-topic or invented tokensFixed k is too tight on flat distributions and too loose on peaked onesA high temperature inflates the tail, so the same p admits far more junk
    When to reach for itGlobal variance control, and generating diverse samples for self-consistency votingCheap hard cap on the candidate set, useful as a safety floorDefault truncation for open-ended text, paired with a modest temperature

    Login to view more content
  • DL0081 Tokenizer Vocabulary Size Effects

    How does the tokenizer vocabulary size affect LLM model quality, memory, and throughput?

    Answer

    Vocabulary size V is one of the few hyperparameters that moves quality, memory, and throughput in opposite directions at the same time, so there is a genuine optimum rather than a “bigger is better” rule. On the cost side, the embedding and unembedding tables grow linearly in V (up to 2Vd parameters when untied), the output projection adds 2Vd FLOPs per token, and the training-time logits tensor of shape b \times T \times V in fp32 becomes one of the largest activations in the whole model. On the benefit side, a larger vocabulary compresses text into fewer tokens, which shortens sequences, shrinks the KV cache, cuts the O(T^2) attention term, and reduces the number of autoregressive decode steps needed to emit the same text. The catch is that compression improves only logarithmically in V while cost grows linearly, and each added token gets a smaller slice of the training signal, so rare embeddings end up undertrained. Empirically the optimum grows with model size: 32k was reasonable for GPT-2-era models, Meta’s Llama 3 moved to 128,256 tokens, and Google’s Gemma 2 uses 256,128, while byte-level and byte-patch models sit at the opposite extreme.

    (1) Memory Cost Is Linear: at d = 4096 and V = 128\text{k}, untied tables hold about 1.05B parameters, roughly 13% of an 8B model, and 2.1 GB of bf16 weights before optimizer state.
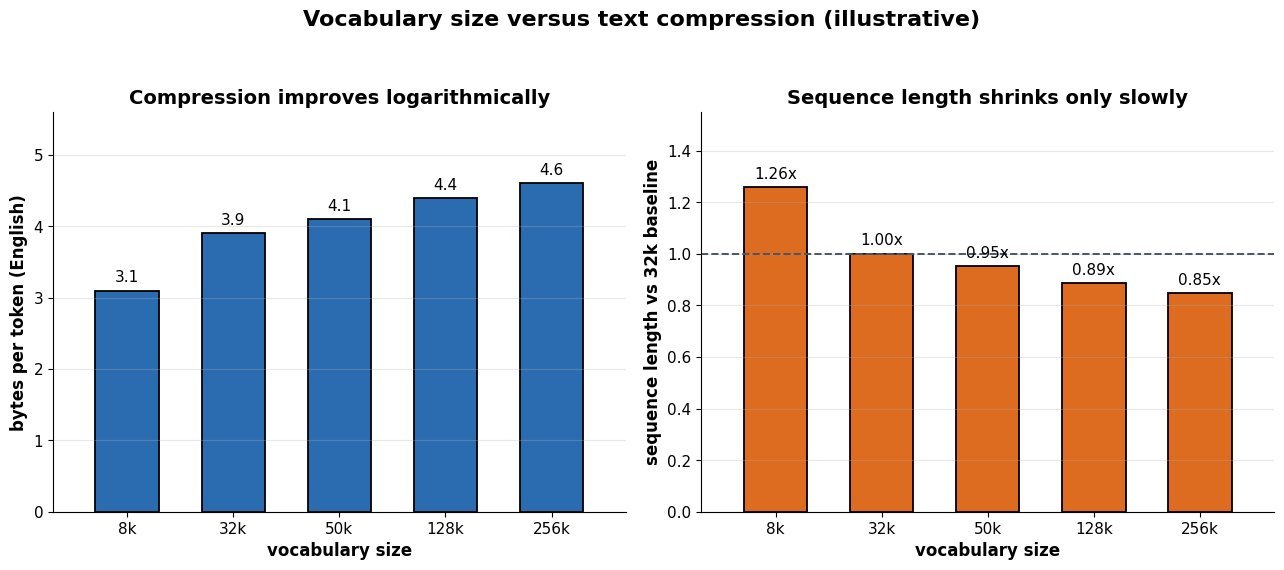
    (2) Compression Gain Is Logarithmic: going 32k → 128k buys only about 11% fewer tokens per document in English, while the embedding tables quadruple.
    (3) The Output Softmax Dominates Small Models: the d \times V projection is about 7% of forward FLOPs for an 8B model but roughly a third for a 1B model with d = 2048.
    (4) Quality Is Non-Monotonic: too small and sequences are long and multilingual fertility explodes; too large and rare rows receive too few gradient updates, producing dead or glitch tokens.
    (5) Throughput Has Two Units: tokens per second falls slightly as V grows, but bytes (or words) per second usually rises because fewer steps are needed for the same text.

    Two bar panels: left panel shows bytes per token rising from 3.1 at 8k vocabulary to 3.9 at 32k, 4.1 at 50k, 4.4 at 128k and 4.6 at 256k; right panel shows relative sequence length for a fixed document falling from 1.26 at 8k to 1.00 at 32k, 0.95 at 50k, 0.89 at 128k and 0.85 at 256k

    Figure 1: Illustrative English compression: quadrupling the vocabulary from 32k to 128k lifts bytes per token from 3.9 to 4.4, which shortens sequences by only about 11%, while the embedding tables grow 4x.

    The most under-appreciated cost is not the weights but the logits activation. Cross-entropy is normally computed in fp32, so a single 8192-token sequence against a 128k vocabulary materializes 8192 \times 128000 \times 4 bytes, about 4.2 GB, and a microbatch of four pushes past 16 GB before the backward pass. This is why large-vocabulary training runs adopt chunked or fused cross-entropy kernels that never hold the full logits matrix, and why teams sometimes cap V purely for activation-memory reasons. At inference the picture flips: the vocabulary contributes a fixed d \times V GEMM per decode step, which is cheap relative to the KV-cache reads in a large model, and the shorter sequence means fewer steps overall, so end-to-end latency for generating a fixed passage typically improves. A separate trap is evaluation: validation loss is not comparable across tokenizers, because the per-token loss is defined over a different unit of text, so comparisons must be normalized to bits per byte or bits per character.

    Mathematical Formulation:
    P_{emb} = 2 V d
    T = B / c(V)
    c(V) \approx a + \beta \log V
    C = 6 (N_{nv} + P_{emb}) T
    M_{logits} = b \, T \, V \, p
    V^{\star} \propto N_{nv}^{0.83}

    Where:

    • P_{emb} is the parameter count of the input embedding plus output unembedding; the factor 2 drops to 1 when the two are tied.
    • V is the vocabulary size and d the model width; N_{nv} is the non-vocabulary (attention plus MLP) parameter count.
    • B is the raw text size in bytes, c(V) the compression ratio in bytes per token, and T the resulting token count; a and \beta are corpus- and language-dependent fit constants.
    • C is approximate training FLOPs under the 6ND rule, which is why a larger V both adds parameters and removes tokens.
    • M_{logits} is the logits activation in bytes, with microbatch b and precision p (4 for fp32); V^{\star} is the compute-optimal vocabulary, whose exponent near 0.83 means it grows more slowly than the rest of the model.
    Two U-shaped curves of relative loss in bits per byte versus vocabulary size on a log-2 axis from 4k to 256k: the 300M non-embedding parameter curve bottoms out near 24k, and the 7B curve sits lower overall and bottoms out near 96k, showing the optimum shifting right with model size

    Figure 2: Illustrative shape of the trade-off at fixed compute: loss measured in bits per byte is U-shaped in V, and the minimum shifts right as non-embedding capacity grows, because a bigger body can afford to spend parameters on the vocabulary.

    PropertySmall BPE (32k)Large BPE (128k-256k)Byte level (256)
    Bytes per token (English)about 3.9about 4.4 to 4.61.0
    Embedding params at d=2048, untied131M525M to 1.05B1M
    fp32 logits per 8192-token sequence1.05 GB4.2 GB to 8.4 GB8 MB
    Average updates per row over 300B tokensabout 9Mabout 1M to 2Mover 1B
    Sequence length for a fixed documentbaseline0.85x to 0.89xabout 3.9x
    Main weaknessHigh fertility on non-English text and codeUndertrained rare rows, huge logits activationLong sequences, many decode steps
    Best fitSub-1B on-device models, single-language domainsMultilingual frontier models with long contextsNoisy input, character tasks, patch-based research

    Login to view more content